2026-10-27 · 15 min · 3d · slam · pose-graph · vggt · feed-forward-reconstruction · long-video

Why read this
Nichelast 15%Rebuilds the two-graph idea on a synthetic loop with known truth: progressive loops cut ATE 5.68 to 1.58 m, shared cameras mostly fix RPE; false loops hurt.
- Original analysis
- Explained from first principles
3D & spatialRuns on a laptop CPUResearch paper
How this was scored
- Is it new?
- 1 of 3: An incremental tweak
- Can I trust it?
- 1 of 3: Spot-checks a few numbers
- Can I run it?
- 1 of 3: API-only, gated or restrictive licence
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 1 of 3: General advice
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 45 of 100, ranked 545 of 621 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
Chen Change Loy posted HiP3R, a training-free way to keep one coherent
scene across thousands of video frames. The paper is arXiv 2610.31635, by Zunnan Xu,
Shangchen Zhou, Yihang Luo and Chen Change Loy (S-Lab, NTU), with a project page. The
post names a code repository, HiP3Rs/HiP3R; I could not open it from this sandbox, so nothing below was read from the
authors' code. What I did read is the paper's HTML, all of its tables, and I wrote a small stand-in for the method and ran it.
Every claim below is labelled. Reported is a number from the paper that I did not re-run. Measured is a number from my own script, on a synthetic backend I built, not on video and not with the authors' pipeline. Reasoned is my arithmetic or inference on the other two.
The problem: local maps in different coordinates
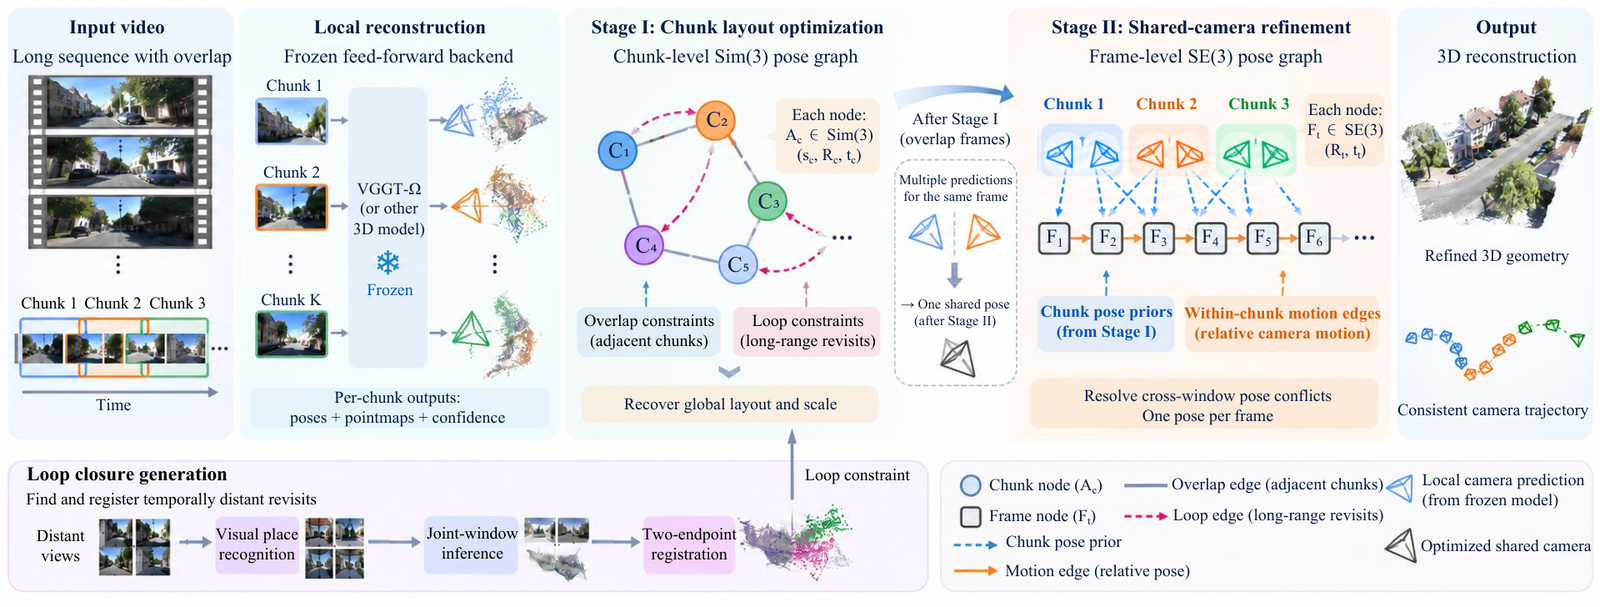
Feed-forward geometry models such as VGGT read a short window of frames and output camera poses and pointmaps in one go. Attention is quadratic in the window, so a video of thousands of frames has to be cut into overlapping chunks. HiP3R's setting is a chunk of 60 frames with an overlap of 30 for VGGT-Omega, and 120 with 32 for LingBot-MAP (reported).
The chunks do not agree with each other. Each is reconstructed in its own coordinate frame, at its own scale, and the frames in an overlap get two predictions, one from each chunk. The paper names three things that go wrong:
- Drift along the chain. Align chunk 2 to chunk 1, chunk 3 to chunk 2, and so on, and scale and orientation errors accumulate.
- Loops that do not close. When the camera comes back to a place it has been, the chain disagrees with itself. Adding every long loop constraint at once to an unaligned chain makes the optimisation non-convex and can diverge.
- Two cameras for one frame. A rigid similarity per chunk preserves the chunk's inside up to scale. If the inside is bent, two chunks disagree about the same frame no matter how well each is placed.
HiP3R answers with two graphs, solved one after the other.
Stage I: a graph of chunks
Each chunk k is a node with a similarity transform A_k = (s_k, R_k, t_k) that maps its local coordinates to the world:
x_world = s_k R_k x_local + t_k. Seven numbers a node. Chunk 1 is fixed as the world frame and scale reference.
Edges are measured relative transforms. Overlap edges join consecutive chunks. The two chunks predict the same pixels in the shared frames, which gives paired 3D points; the paper fits the relative similarity with confidence-weighted, Huber-reweighted Umeyama alignment on a bounded number of points, not on every pixel. Loop edges join chunks that revisit a place: visual place recognition proposes frame pairs, the temporal neighbourhoods of both ends go into one joint backend call, and the two endpoints are registered back to their original chunks (reported).
The residual of an edge is seven numbers, rotation (3), translation (3) and log-scale (1), under a Huber loss, with a bounded weight per loop based on its registration residual. It is solved with trust-region reflective least squares over a sparse Jacobian.
The part I found most useful to know is the schedule. Adjacent edges stay on throughout. Loops come in by increasing temporal span, each stage starting from the last solution. The reason given is the one in the problem list: far loops on an unaligned chain are a bad start for a non-convex solve.
Stage II: one camera per frame
Fix the chunk layout. For each frame t there is one camera F_t in SE(3), rigid, no scale. Each chunk that saw the frame contributes two kinds of factor:
- a placement prior: the chunk's own prediction, moved to the world by its stage-I transform, pulls on F_t;
- a motion edge between consecutive frames of a chunk: the relative pose the chunk predicted should hold between the shared cameras.
Priors keep the trajectory on the recovered layout; motion edges keep it smooth across chunk seams. For long sequences
only a keyframe subgraph is optimised and the corrections are interpolated to the rest. The pointmaps are then moved with
the cameras: placed by A_k, then corrected by F_t Q^-1, so depth and chunk scale are kept.
That is the whole method. Everything is on top of frozen predictions: no fine-tuning, and it runs behind a chunked backend or a streaming one.
What the paper reports
The headline, macro-averaged over seven datasets and 61 sequences with VGGT-Omega as the backend (reported, Table 1): ATE 18.555 to 4.906 m, a 74% cut; rotation RPE 1.820 to 0.590 degrees; translation RPE 0.9878 to 0.0622 m, a 94% cut. With LingBot-MAP, ATE 8.288 to 4.017 m. On the compact indoor sets there is little to fix: native VGGT-Omega already has 0.037 m on 7-Scenes and 0.019 m on Neural RGB-D.
The ablation I find most informative is the stage-wise one, Table 6, on identical VGGT-Omega predictions. Drag through it:
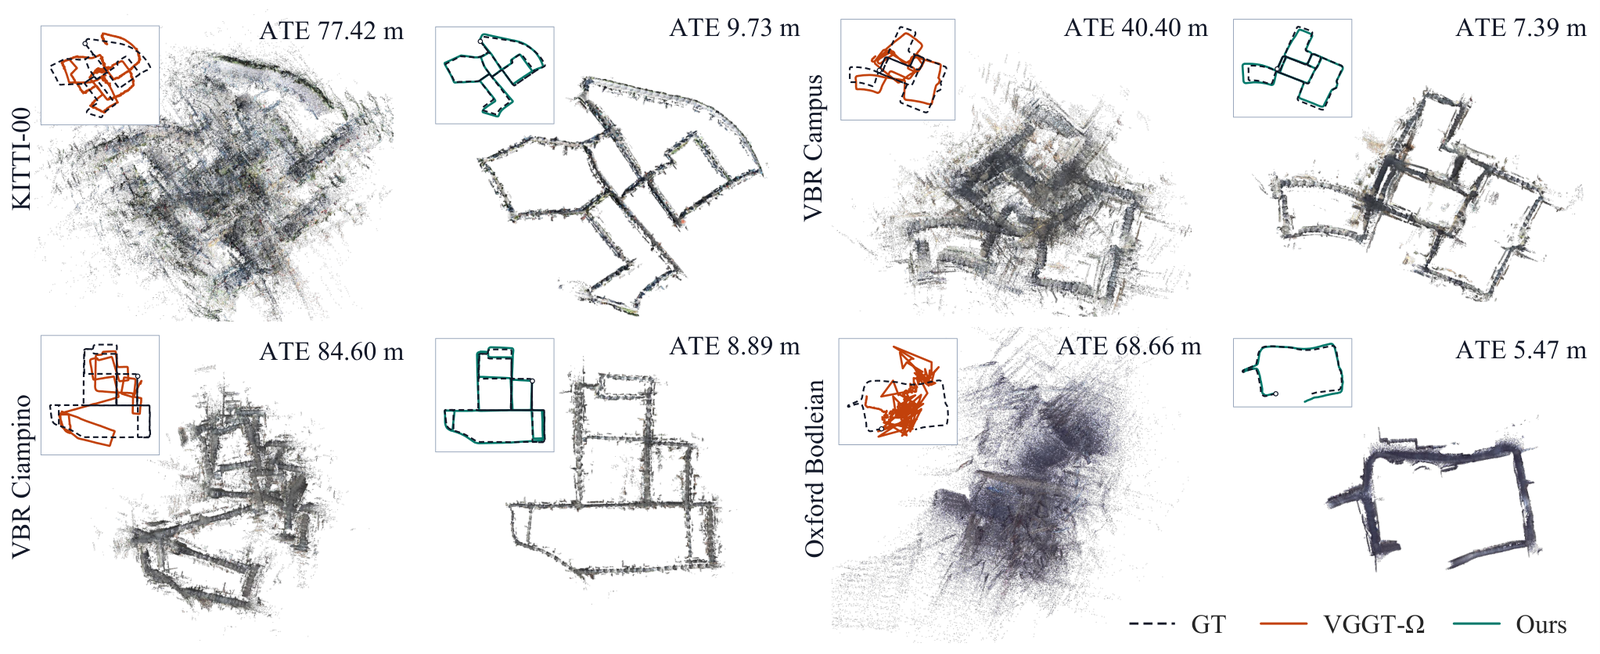
Read it as the paper's own split of labour (reported). The chunk layout does nearly all of the ATE work: KITTI goes from 77.42 to 9.75 m, Oxford from 9.861 to 1.599 m, VBR from 41.91 to 22.44 m. The shared camera then moves ATE by 0.2% on KITTI, 0.0% on VBR and 1% on Oxford. What it does change is the relative error: rotation RPE down 24% on KITTI, 30% on Oxford, 5% on VBR, and translation RPE down 29%, 40% and 22%. That is the job the paper assigns it, resolving cross-window conflicts, and the table shows it doing that and little else.
Two more tables matter for how to read the headline.
- Against VGGT-Long (Table 2, same VGGT-Omega backend): with loops, VGGT-Long gets KITTI to 10.19 m and VBR to 41.27 m; HiP3R gets 9.730 and 22.44 m. On KITTI that is 0.46 m of difference, and on VBR it is nearly half. The part of the headline that comes from simply having loop closure at all is the 110.3 to 10.19 m step, which VGGT-Long's own loop version already takes.
- The shared-camera design (Table 5): Layout Only, Single, Unary, Motion and Shared. Motion-only (no placement priors) gets slightly lower relative errors but its ATE jumps to 11.678 m on VGGT-Omega and 6.501 m on LingBot-MAP, against about 4.9 and 4.0 for the others. Priors anchor the layout, motion edges smooth it, and each is bad alone.
The cost side (Table 4, extended sequences): bounded point sampling cuts graph build and solve from 12,232.18 to 2,004.20 s with ATE 21.7751 to 21.7569 m, and the complete solver reaches 17.4708 m in 753.43 s. The paper's own conclusion lists what is missing: online updates, and robustness to unreliable loop closures.
What I built: the same two graphs on a backend I control
Real numbers need real video, a GPU and the weights. I have none of those here, so I did the next most useful thing: wrote
the two-graph idea from the paper's section 3 in about 300 lines of NumPy and SciPy, and ran it on a simulated chunked
backend where the true trajectory is known. This is our simplified re-implementation, not the authors' pipeline. The
file is chunkgraph.py; one seed takes about two minutes on one CPU thread.
The world. 800 frames, 1 m apart, two laps of a closed loop about 64 m in radius (so the second lap lies on the first and every chunk in lap one has a revisit in lap two). Chunks of 40 frames with an overlap of 20: 39 chunks. I used a shorter chunk than the paper's 60 and 30 to keep the graph small.
The backend. For each chunk I draw an arbitrary local frame (a random rotation, a random translation, and a random
scale about exp(N(0, 0.4))). Predictions are the ground truth moved into that frame, plus errors that a rigid transform
cannot undo:
- a rotation random walk inside the chunk, 0.12 degrees a frame;
- per-frame rotation noise of 0.08 degrees and translation noise of 0.04 m;
- a scale that drifts linearly across the chunk, with a slope drawn from
N(0, 0.03); - twelve scene points per frame, with 1% depth noise, so each frame's pointmap is tied to its own (wrong) camera.
All numbers are my choices. The point is that each chunk is bent inside, which is the situation the paper argues for.
Stage I. Overlap edges come from a Huber-reweighted Umeyama fit of up to 200 shared points. The chain is the
initialisation. Loop edges: for every chunk pair at least 150 frames apart whose middle frames are within 8 m, one per
chunk (19 loops), I give the graph the relative pose between the two revisit frames (truth plus 0.3 degrees and 0.5 m of noise)
and solve for the similarity that makes the two chunks' own predicted cameras obey it, which is the role of the paper's
joint-window registration. That is generous to loops: place recognition is assumed to be right. The solve is
scipy.optimize.least_squares with a Huber loss, a sparse Jacobian pattern and the first chunk fixed. Progressive
loops: three stages, shortest span first, a third each, adjacent edges always on.
Stage II. One SE(3) variable per frame (800 frames, 4,800 parameters), unary priors from every chunk that saw the frame, and relative-motion edges inside each chunk, the same factors as the paper's equations 4 to 6. No keyframe subgraph.
Metrics. ATE after a Sim(3) fit to ground truth, rotation RPE in degrees and translation RPE in metres at a one-frame gap, as in the paper. Six seeds. Each number below is the mean, with the range over seeds in brackets (measured).
| Stage | ATE (m) | RPE rot (deg) | RPE trans (m) |
|---|---|---|---|
| 1. Chain only | 5.68 [3.13, 8.76] | 0.314 | 0.137 |
| 2. + all loops at once | 2.63 [1.02, 3.17] | 0.312 | 0.172 |
| 3. + progressive loops | 1.58 [1.02, 2.58] | 0.309 | 0.160 |
| 4a. + camera graph, priors only | 1.43 [0.85, 2.32] | 0.222 | 0.126 |
| 4b. + camera graph, motion only | 1.54 [0.97, 2.54] | 0.215 | 0.114 |
| 4c. + camera graph, both (shared) | 1.43 [0.85, 2.34] | 0.208 | 0.108 |
Here is one of the six runs, drawn top-down. Both laps trace the same curve, so a trajectory that closes its loop shows one curve and one that does not shows two:
What the numbers say
- Loops are where the ATE goes. The chain gives 5.68 m on a 400 m loop; loops cut that to 1.58 m, 72%. That is the paper's pattern (stage I does almost all the ATE) reproduced in miniature, which is a check on my implementation rather than on theirs.
- Progressive loops beat all-at-once here, 1.58 against 2.63 m, and in every one of the six seeds the progressive run was at least as good as the all-at-once run. The paper's Table 4 reports its progressive scheduling mainly saving time on its data, with ATE 21.7770 to 21.5241 m, so the size of the accuracy effect differs between the two settings. I cannot say which parts of mine are due to the simulation.
- Loops hurt the relative error before stage II repairs it. Translation RPE goes 0.137 (chain) to 0.172 (all loops): the loops drag chunks into place and open small steps at the seams. The camera graph brings it to 0.108, below the chain, and rotation RPE falls from 0.31 to 0.21 degrees. Stage II leaves ATE essentially where stage I put it: 1.58 to 1.43 m. The same division of labour as Table 6, again in miniature.
- Shared against the one-sided variants. Shared has the best relative errors on translation and rotation by small margins and ties priors-only on ATE. Motion-only did not blow up. The paper's Table 5 has motion-only ATE going from 4.9 to 11.678 m, and mine goes from 1.58 to 1.54. I did not reproduce that effect. A likely reason (reasoned) is that my solver starts at the layout and is capped at 15 function evaluations, so a gauge-free problem has little time to wander; I did not test that.
One overlap, up close
Why does one camera per frame help at all? Because the two chunks disagree about the same frame. The widget plots one overlap from the run above: the distance from ground truth of each chunk's placed prediction, and of the shared camera, over the 20 shared frames.
In that overlap the two placed predictions are 0.45 m apart on average (measured, one overlap of one run), and their errors against ground truth average 2.59 and 1.86 m. The shared camera sits between them at 2.22 m: it does not find the better chunk, it removes the disagreement. That is what one pose per frame can promise. If both chunks lean the same way, the shared camera leans with them, and only loops can say otherwise. It is the reason ATE barely moves in the second stage while RPE does.
A harder setting, and a bad loop
Two more runs of the same script, same measuring (measured, means over seeds).
Twice the in-chunk drift (--drift 2.5: rotation walk and scale slope times 2.5, six seeds). The chain is now 13.77 m
[8.30, 21.65]. All loops at once: 6.99 m. Progressive: 6.17 m. Shared cameras: 6.00 m [2.07, 8.18]. The ordering is the
same. Progressive was at least as good as all-at-once in all six seeds. The relative errors tell a less comfortable story
than in the base run: rotation RPE goes 0.646 to 0.438 degrees with the camera graph, but translation RPE ends at 0.263 m,
against 0.248 m for the plain chain. The loops opened seam steps that one camera per frame closed only to the chain's level.
Wrong loops. Each candidate loop becomes a false match with probability 0.15, with a 20 degree and 20 m error in its relative pose, which is what a bad place-recognition hit would hand the graph. Four seeds, 2 to 4 false loops of 19 each. Chain 5.54 m, progressive loops 6.96 m, shared cameras 6.82 m. Two seeds are better than the chain (4.00 to 2.68 m and 5.37 to 3.38 m), two are much worse (6.49 to 9.39 m and 6.30 to 11.85 m). My robust loss, Huber with a scale of 3 normalised units, did not contain a 20 m error. In my setup, three bad loops outweigh sixteen good ones. The paper gives each loop a bounded weight from its registration residuals and names unreliable loops as future work; I did not implement the weights, so this run shows the exposure and nothing about how well their weights would hold.
What I did not run
- Nothing from the authors' code. I did not run HiP3R, VGGT-Omega or LingBot-MAP, and did not reproduce any number from the paper. Every table in the previous section is from a simulation with errors I chose.
- No real place recognition. Loop candidates are handed over from ground truth. The paper's own conclusion names robustness to unreliable loops as open work, and my false-match run above is only a first look.
- No keyframe subgraph, no point-sampling bound, no solver restarts. The paper's timings (Table 4) come from sequences of tens of thousands of frames; mine take two minutes for 800.
- The error model is mine. A random walk, a linear scale drift and iid noise. Real feed-forward errors are structured by the scene, and that is what the paper's benchmarks have and mine do not.
What to take from it
- Treat chunk placement and per-frame consistency as two problems. The reported tables and my own run agree on this one: the Sim(3) graph decides where things are, and the shared-camera graph decides how smoothly the camera moves through them. If you only need a map, the first stage is the one to build: on KITTI it is the 77.42 to 9.75 m step.
- Order your loop closures. Short spans first costs nothing and, in my simulation, was never worse than all at once. The paper's own justification is the non-convexity of far loops on an unaligned chain.
- Keep placement priors in the camera graph. The paper's Table 5 shows motion-only ATE going to 11.678 m. My version did not reproduce that, so I would not drop the priors on the strength of my run.
- Plan for bad loops. The method's weak point, by the authors' own account, is a loop that should not exist.
The code for my experiment is the file above; the paper's own repository, if the post's link is right, is the place for anything you want to trust.