2026-09-22 · 14 min · world-models · video-generation · diffusion · architecture · explainer
Four days ago I wrote up
XGEN-JING and DAO — the renderer shipped, the world
engine did not — and in the middle of it was a small observation about the
control surface. jing_flash_v1/config.json declares a six-dimensional camera
control vector, and the parser that fills it populated two dimensions:
# models/control.py at the 17 September release
return [
    float(("d" in keys) - ("a" in keys)),  # strafe
    0.0,
    float(("w" in keys) - ("s" in keys)),  # forward / back
    0.0, 0.0, 0.0,
]
On 20 September, commit cbeec31 landed, titled "fix: remove unintended
limitations and clean up prompt skills". Ten files, and the one that matters
is that function:
# models/control.py at cbeec31
"""Map simultaneous WASD/IJKL keys to [tx, ty, tz, pitch, yaw, roll]."""
return [
    float(("d" in keys) - ("a" in keys)),
    0.0,
    float(("w" in keys) - ("s" in keys)),
    float(("i" in keys) - ("k" in keys)),   # pitch — look up / down
    float(("l" in keys) - ("j" in keys)),   # yaw   — turn left / right
    0.0,
]
Four hard-coded zeros became two, so the live axes go from two of six to four of
six. The commit also adds
examples/train_carriage_gaze.json, whose second chunk is "control": ["j","j","j"]
and whose fourth is ["l","l","l"] — an example that exists, as far as I can
tell, to exercise the axes the commit unlocked. This piece is about what those
six slots are attached to, which turns out to be a lot more model than the
two-line diff suggests, and about the parts of the conditioning interface I did
not take apart the first time.
- license
- custom
- branch
- main
- tests
- none found
- source
- 164.9 kB
- commit date
- 2026-09-20
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-09-22 at cbeec31 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile
Three hundred million parameters behind six numbers
I pulled the safetensors headers out of all fifteen shards over HTTP range requests rather than trusting the Hub's metadata, which returns empty for this repo. The totals:
| tensors | parameters | |
|---|---|---|
transformer_blocks | 600 | 32,278.6 M |
token_refiner | 21 | 770.7 M |
control | 408 | 302.6 M |
norm_out | 3 | 28.9 M |
context_embedder | 2 | 27.5 M |
time_embedder | 4 | 15.8 M |
| everything else | 8 | 1.4 M |
| total | 1,046 | 33,425,588,992 |
So the exact parameter count is 33,425,588,992 — 33.408B in BF16 plus 17.3M kept in FP32 (the time embedder, the video and audio in/out projections). My earlier piece put it at "~33.4B" from dividing 66.9 GB by two bytes; that back-of-envelope was right to three significant figures, and now it does not need to be an envelope.
The control group is the interesting row. Its 408 tensors are eight in a
shared encoder and eight each in fifty block injectors — one per
transformer layer, matching num_layers: 50. Each injector is a FiLM:
# models/control.py
class FiLM(nn.Module):
    def __init__(self, control_dim, hidden_dim):
        self.mlp1 = nn.Linear(control_dim, control_dim)     # 512 → 512
        self.mlp2 = nn.Linear(control_dim, control_dim)     # 512 → 512
        self.scale = nn.Linear(control_dim, hidden_dim)     # 512 → 5376
        self.shift = nn.Linear(control_dim, hidden_dim)     # 512 → 5376
        nn.init.zeros_(self.scale.weight); nn.init.zeros_(self.scale.bias)
        nn.init.zeros_(self.shift.weight); nn.init.zeros_(self.shift.bias)
6,041,088 parameters each, times fifty, plus 541,696 in the encoder, is
302,596,096 — 0.91% of the checkpoint, devoted entirely to making six
numbers modulate every layer's hidden state. The zero-initialised scale and
shift are the ControlNet-family trick: at initialisation the injector is the
identity, so control can be trained into a finished model without breaking it.
Two details in that encoder are worth reading as archaeology. The input
projection is [512, 6] — six in, exactly as the config declares, and Control
refuses to build with any other dim_in. And sitting beside it is a second,
larger projection that is never called:
# models/control.py — ControlEncoder.__init__
self.input_proj = nn.Linear(dim_in * t, dim_out)
# Retained because control state dictionaries contain this projection.
self.dense_input_proj = nn.Linear(dim_in * t * h * w, dim_out)
dense_input_proj.weight is [512, 24] in the shipped checkpoint — 6 × 1 × 2 × 2,
so patch_size = (1, 2, 2) — and 12,800 dead parameters. A dense input
projection takes one control value per spatial patch rather than one per slice.
Somebody trained a per-patch control path, and what shipped uses the per-slice
one. That is a bigger hint about where this model is going than either of the
two axes the commit turned on.
The conditioning interface is text, almost all the way down
The README's one-sentence summary is: "Given actions, reference images, and observation history, JING generates first-person video and audio." Having now read the packer and both shipped examples, here is what each of those three is in practice.
An action is a prompt chunk. Not a symbol, not a verb from a vocabulary —
a paragraph. expand_slices() accepts exactly three keys per chunk and nothing
else:
if not isinstance(chunk, dict) or set(chunk) - {"prompt", "repeat", "control"}:
    raise ValueError(f"Chunk {index}: only prompt, repeat and control are accepted")
The prompt itself is structured, but structured as prose, with three named
sections the prompt skill compiles into: integrated_multimodal_description,
overall_soundscape, and non_diegetic_music. Camera framing, who is in
shot, whose lips are closed, and what the room sounds like all arrive as
English sentences.
Dialogue is a tag inside that string. This is the part I did not expect:
Current speaker: Clara (S2, warm clear adult female voice). Clara looks at me
and replies with a welcoming expression: <d>[English] I'm Clara, the town's
teacher. Welcome to town!</d> Only Clara speaks. I listen silently…
There is no dialogue field, no speaker id, no audio input. A line of speech is
<d>[English] … </d> inside the prompt, and the voice is described next to
it in words — "warm clear adult female voice". The soundscape is the same:
overall_soundscape: Only Clara's warm female voice, over faint oven crackle.
The audio half of "video and audio generated together" is conditioned entirely
through the text encoder.
That said, the joint generation itself is not a bolt-on. The transformer has
audio_proj_in [5376, 32] and audio_proj_out [32, 5376] beside the video
proj_in [5376, 96] and proj_out [96, 5376] — a 32-channel audio latent
and a 24-channel video latent (96 = 24 × 2 × 2 patch) entering and leaving the
same fifty-layer trunk. Audio and video are not two models stitched at the
output; they are two token streams through one stack, which is what
audio_in_channels: 32 in the config means and why the pairing is in sync at
all.
Reference images are prepended at negative time. ref_image_slots: 5
inside reserved_slots: 15, and the packer places them like this:
# models/packing.py
ref_pos[:, 0] = -generation["reserved_slots"] + index
Reference frames occupy temporal positions before frame zero, at
reference_timestep: 0.0 — that is, as clean, fully-denoised context — with
the text tokens packed below them at more negative indices still. They are
addressed from the prompt as <Picture 1>, <Picture 2>, up to five. So the
scene, the character and the object you hand it are literally the first things
on the timeline.
XGEN's research page demonstrates exactly that three-slot case, and publishes the inputs beside the output.
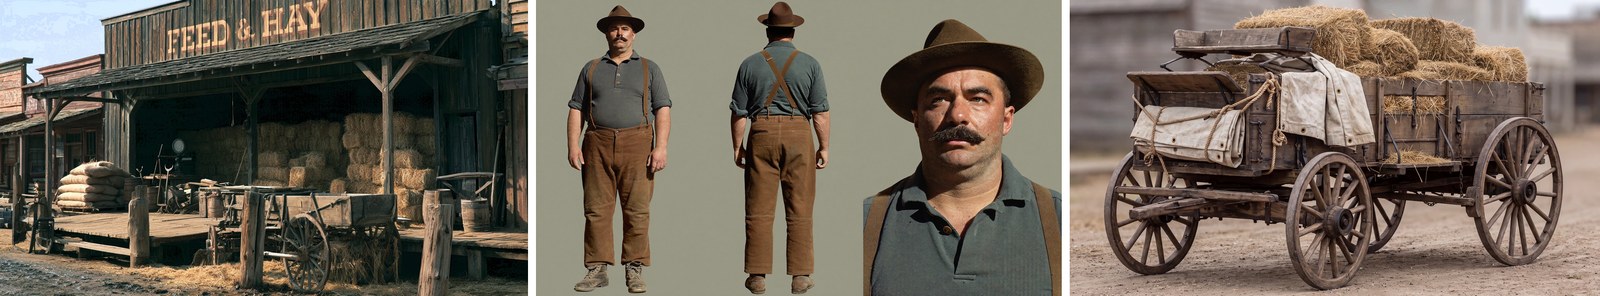
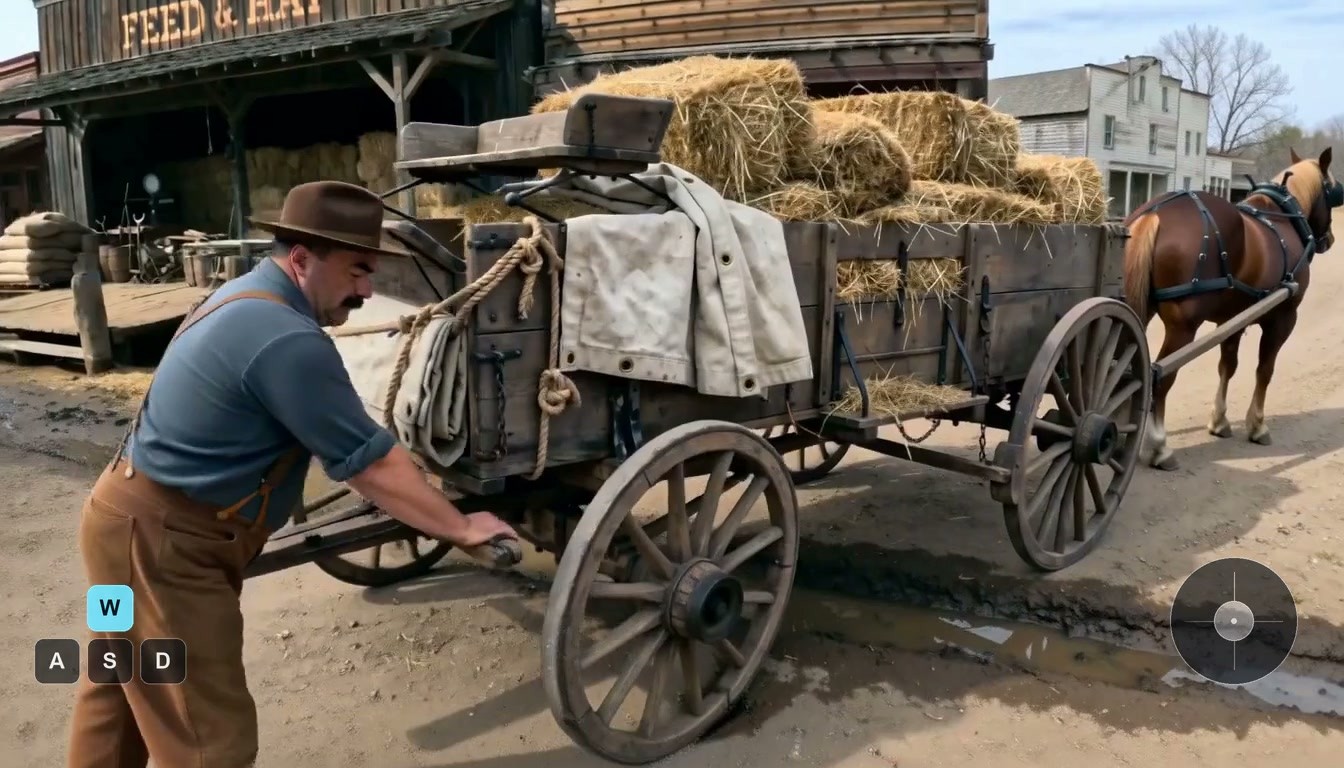
Observation history is the clip so far, which in this release means the rest of the same tensor.
What "interactive" costs
The layout formula is in the README — num_frames = 17 * sum(repeat) + 5 —
and it checks on both shipped examples: bakery_greeting sums to 21 repeats
and declares 362 frames, train_carriage_gaze sums to 29 and declares 498.
The prompt skill fixes the frame rate: "The compiler targets 24 FPS with
generation.first_chunk_size=2."
So one control slice is 17 frames, 0.708 seconds. That is the finest interval at which a key, a line of dialogue, or the soundscape can change. It is not a latency in the usual sense — it is a quantisation. Even a perfectly responsive causal build of this architecture could not react to a keypress sooner than the next slice boundary, because the slice is the unit the control vector attaches to. For comparison, a 60 Hz game loop's input-to-photon budget is around 50 ms; this is fourteen times that, before any model has run.
The wall clock is the part nobody has published. The demo is validated on six H100s — one for the text encoder, one for the video and audio VAEs, four for the DiT under sequence parallelism, FlashAttention-4 as the default backend — and there is no throughput number in the README, the model card, or the repository. The four-step FlashGen distillation is there to make it fast, and the WBench entry that ranks #1 is the bidirectional variant. I cannot run it and will not guess at it.
What the code does settle is the shape of the latency, and it is the same finding as four days ago from a different angle:
# models/attention.py
out, _ = flash_attn_func(q, k, v, causal=False)
Non-causal attention over the packed clip means frame 1 depends on frame 362.
There is no prefix you can emit early. Time-to-first-frame equals
time-to-last-frame, whatever that is, and the round trip for any action is
the generation of everything after it as well. The README is straight about
this — "This release provides four-step bidirectional inference… The causal
model and technical report are coming soon" — and pipelines/bidirection.py
reads a static JSON file of pre-written chunks, encodes the whole thing,
denoises it in four steps and decodes one finished clip.
- task
- image-text-to-video
- library
- diffusers
- license
- other
- safetensors
- 15 shards
- largest file
- 4.93 GB
- files
- 28
- downloads
- 2
- likes
- 166
- languages
- en, zh
Fifteen BF16 shards, 66,885,622,272 bytes by the index's own total_size, 1,046 tensors, 33,425,588,992 parameters. The repo README still lists the causal model and the technical report as coming soon.
repo last modified 2026-09-20
The part that reads as a correction
I want to be careful about causation here, because it would be flattering and almost certainly wrong to claim any. This site published on 18 September; the commit landed on 20 September; its title is "fix: remove unintended limitations". Four axes that the architecture reserved, the parser zeroed and the README did not mention were, by XGEN's own description, unintended. A project that ships a control interface with two of six dimensions live and then connects two more within a working week is a project moving fast, not one reacting to a blog.
What I will say is that the change is exactly the kind a reader can check, and that the README changed with it rather than after it:
Two slots remain literal zeros: ty, which would be rise and fall, and
roll. For a first-person model, roll being absent is a reasonable product
decision — people do not tilt their heads sideways much and a world model that
lets you is a world model that will make you ill. Vertical translation is a
harder omission to explain, since crouching, standing and stairs are all
egocentric primitives, and the stairway shot in XGEN's own hero loop climbs.
The last thing in that commit worth pointing at is prompt_skills/SKILL.md,
which is an agent skill in the Claude Code sense — YAML frontmatter with
name and description, a workflow to run, three prompt files to edit when
you want different generation behaviour. Its job is to turn a story and some
reference images into a validated cases JSON. Given that the conditioning
interface for this model is paragraphs of English with dialogue tags in them,
shipping a language model's instructions as part of the release is not a
novelty item. It is the compiler.
What would change my mind
5 claims above, and what would falsify each
Commit cbeec31 (20 September 2026) connected pitch and yaw to i/k and j/l, taking JING's live control axes from two of six to four of six; ty and roll are still literal zeros.
Read from
git show cbeec31 -- models/control.pyagainst the release tree. A later commit wiring the remaining two, or evidence thattyandrollare populated somewhere else in the pipeline before the tensor reachesControlEncoder, would overturn it. I tracedcontrol_vector()as the only producer.XGEN-JING is exactly 33,425,588,992 parameters, of which 302,596,096 (0.91%) are the camera-control branch.
Computed from the safetensors headers of all fifteen shards, fetched by HTTP range request: 1,046 tensors, 33.408B in BF16 and 17.3M in FP32. Load the checkpoint and sum
p.numel(); if the total differs, the headers were read wrong. Note the scope — this is the JING transformer only. The text encoder, the tokenizer and both VAEs come from Diffusers-format MiniMax-H3 and are not counted.Dialogue and audio are conditioned purely through the text prompt: speech is a <d>[English] …</d> tag inside the prompt string and the soundscape is a sentence describing it. There is no audio conditioning input.
Both shipped example cases are structured this way, and
expand_slices()rejects any chunk key butprompt,repeatandcontrol. What would falsify it is an audio input path anywhere inpipelines/bidirection.py— a reference waveform, a speaker embedding, a prosody control.audio_proj_inexists, but it is the audio latent stream through the trunk, which is generation, not conditioning.The finest interval at which anything in a JING clip can change is 17 frames — 0.708 s at 24 fps — because the control vector attaches to a slice.
From
num_frames = 17 * sum(repeat) + 5in the README, verified against both examples (21 repeats → 362 frames, 29 → 498), and the prompt skill's statement that the compiler targets 24 fps. A build that accepts a per-frame control timeline — which the deaddense_input_projhints was trained at some point — falsifies it immediately.No throughput figure for JING has been published: the demo is validated on six H100s and neither the repo, the model card nor XGEN's pages give a wall clock.
An absence claim about four sources I read on 22 September 2026. One benchmark line from XGEN, or one reproduction with a timer, settles it — and it is the single number I most want, because "interactive" and "seconds per frame" are different products and nothing public distinguishes them.