2026-10-24 · 19 min · training · theory · optimization · distillation
A 1:51 narrated explainer, drawn in code. Every number and picture in it is this article's own; the sources are below.
› transcript
Hi, I'm Coaming! Standard cross-entropy has a gradient that can silently round to zero. Here is how, and the fix. The standard code adds a tiny number to one, and it vanishes. The fix never adds the one. Here m is the margin: how far the right logit sits above the others. The usual form adds e to the minus m to one. In float thirty-two, past a margin near sixteen point six, that sum is one, and the gradient zero. The fixed form keeps e to the minus m on top, accurate until the exponent runs out. After memorising, margins grow past the cliff, and the target gradients go to zero. With almost no gradient, Adam's running average of squared gradients decays. Weight decay pulls a few examples back, and their gradients switch on again. Adam divides them by that tiny average. The step is huge, the loss spikes, and it repeats. Bug two is in distillation. Student and teacher are rounded separately, then subtracted, so even a perfect match leaves a gradient. The fix starts from the logit gap, in log space, so equal logits give exactly zero. In the paper's runs, the standard margin saws up to the cliff and falls back. The fixed loss crosses smoothly. On a shared cloud CPU, standard cross-entropy slingshot six times in every seed, the fixed loss never. But in my runs the fix did not speed up grokking. If the number you need is tiny, compute it directly, never as one minus something close to one. A gradient that rounds to zero, Adam turning it into slingshots, and a rewrite. Every source is in the full article. I'm Coaming. Bye!
Why read this
Essentialtop 10%Both bugs reproduced in PyTorch with printed values, the fix ported and checked, and a CPU grokking run: slingshots gone, but no speed-up here.
- Checked against the source
- Runs on a laptop CPU
- Interactive explanations
Training & RLPractitioner paper
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 3 of 3: Reproduces the headline result, or shows from primary files it is wrong
- Can I run it?
- 3 of 3: Open, permissive, runs on reader hardware with instructions
- Will I understand it?
- 3 of 3: Mechanism carried by interactives built from real code or data
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 3 of 3: Evergreen fundamentals
- Does it affect many?
- 2 of 3: A widely used model, tool or lab release
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 87 of 100, ranked 7 of 607 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
A Fix for Softmax and Cross-Entropy (Jonathan T. Barron, Dan Gnanapragasam, Michael Tschannen, Google DeepMind, arXiv 22 October 2026) makes a claim that sounds like it cannot be true: the softmax and cross-entropy in JAX, PyTorch and the textbooks are wrong in two places. Not unstable in some exotic regime. Wrong, in the sense that they return a different gradient from the one the formula defines, in a regime that ordinary training reaches.
Barron announced it on X on 23 October: "all existing implementations of softmax and cross-entropy (that's JAX, PyTorch, textbooks, etc) have a subtle bug --- two bugs, actually. A simple rewrite fixes both, and eliminates 'slingshots' when grokking." The HTML version of the paper carries the code, and there is an interactive demo.
I wanted to see the numbers myself, so this page has three kinds of evidence, each labelled. Measured: I ran it, in PyTorch 2.14.1 (CPU build) and NumPy 2.5.4 on a shared 4-core cloud VM, with no GPU. Reported: the paper's figure, not re-run. Reasoned: my arithmetic on the other two.
Softmax as everyone writes it
Take logits . Computing directly overflows once a logit passes about 88 in fp32, so every framework first subtracts the largest logit:
Cross-entropy against a target distribution is , and its gradient is the cleanest result in deep learning: . and each sum to one, so the gradient sums to zero. Raising one logit has to lower the others. Keep that invariant in mind; both bugs break it.
Bug one: Softmax Collapse
Call the target class and suppose the model is right and confident, so . The paper measures confidence with the logit margin, how far the target logit sits above the log-sum-exp of all the others:
After the max shift, the target's own term in the denominator is and the other terms add up to exactly . So the denominator is , and the hard-target loss and gradient are
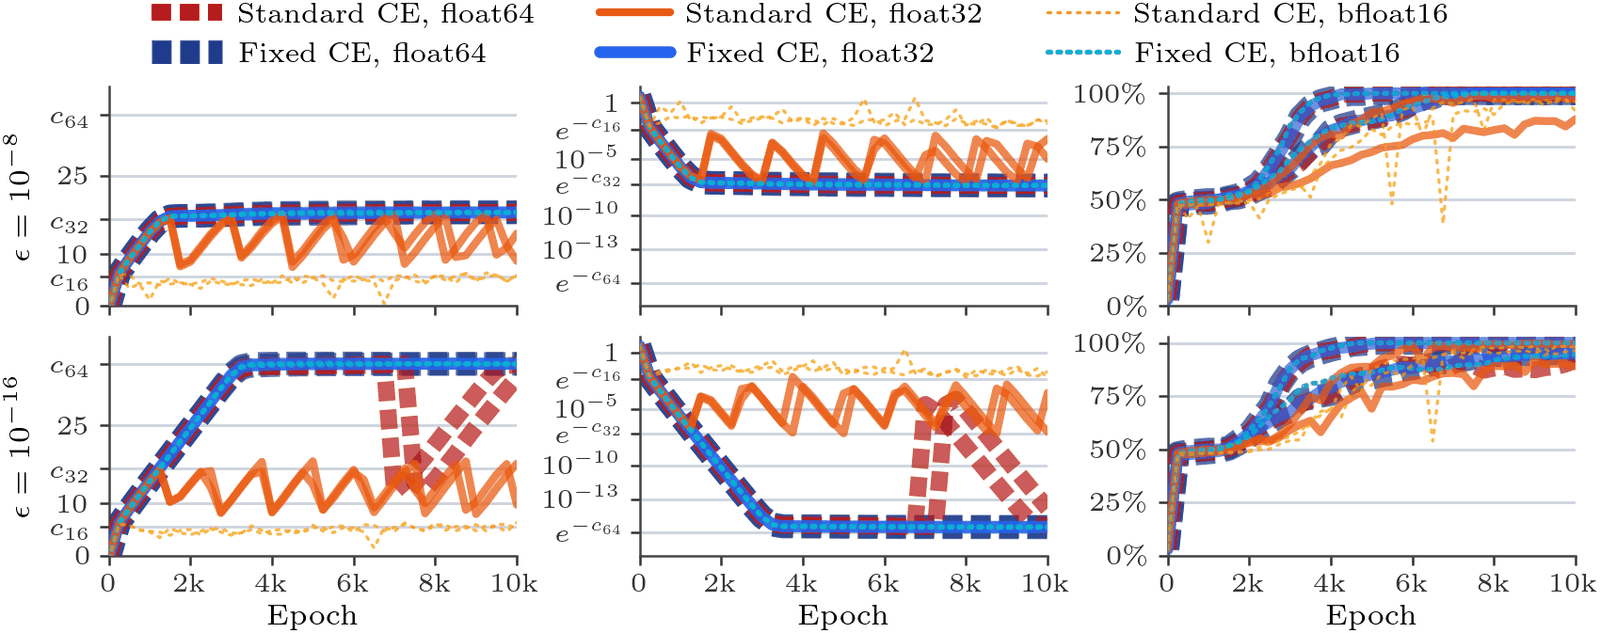
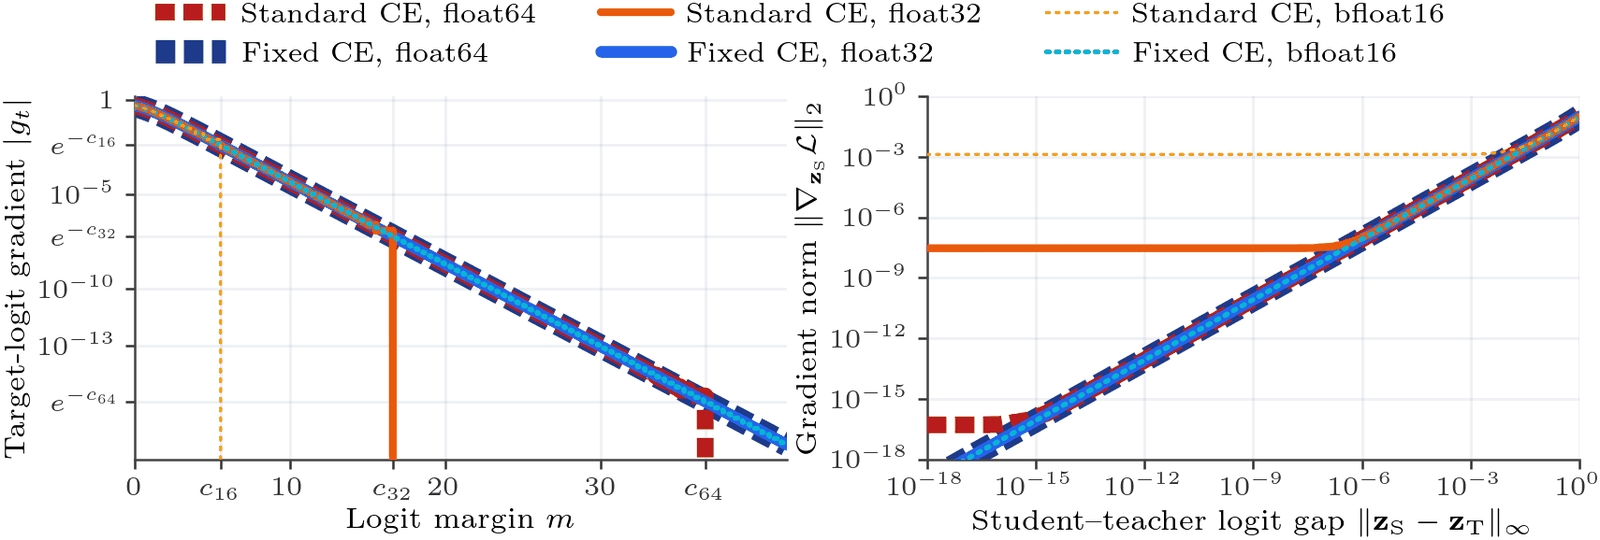
The two forms of are equal on paper. In floating point they are not. Floats are dense near zero and sparse near one: fp32 can hold numbers as small as about , but the gap between 1.0 and the next float is . Add anything at or below to 1.0 and the sum rounds back to exactly 1.0. That happens once , which is (reasoned). The paper calls this the precision cliff and gives for bf16, for fp32 and for fp64 (reported; and match, reasoned).
Past the cliff the standard path computes , subtracts 1, and gets a target gradient of exactly 0.0. The loss is as well. But the non-target gradients are each divided by 1.0. That numerator was never added to 1, so it stays a perfectly good small positive number all the way down to exponent underflow near . The row of gradients now sums to . The invariant is gone.
What PyTorch prints
Here is the paper's own example, with target 0, so , run through torch.nn.functional.cross_entropy and through my PyTorch port of the fix (measured):
-- torch.float32
torch.log_softmax(z)             [ 0.0000e+00, -1.8000e+01, -1.8000e+01]
log_softmax_fixed(z)             [-3.0460e-08, -1.8000e+01, -1.8000e+01]
F.cross_entropy     loss=0.0000e+00 grad=[ 0.0000e+00, 1.5230e-08, 1.5230e-08] sum=3.0460e-08
cross_entropy_fixed loss=3.0460e-08 grad=[-3.0460e-08, 1.5230e-08, 1.5230e-08] sum=0.0000e+00
-- torch.float64
F.cross_entropy     loss=3.0460e-08 grad=[-3.0460e-08, 1.5230e-08, 1.5230e-08]
The fp32 standard gradient is the correct gradient with its first entry deleted. In fp64 the same call is right, because 17.31 is below fp64's cliff. The paper reports the identical numbers from jax.nn and optax (reported), and a NumPy textbook version, q = e / e.sum(); g = q; g[t] -= 1, prints the same [0.000e+00 1.523e-08 1.523e-08] (measured).
bf16 hits it at a margin anyone reaches in minutes. With , (measured):
F.cross_entropy bf16   loss=0.0000e+00 grad=[ 0.0000e+00, 9.1171e-04, 9.1171e-04]
fixed bf16             loss=1.8082e-03 grad=[-1.8234e-03, 9.1171e-04, 9.1171e-04]
exact fp64 grad                         [-1.8204e-03, 9.1022e-04, 9.1022e-04]
The widget below does the same arithmetic in your browser, one rounding at a time, for three classes. Drag the margin across the cliff and watch the standard target gradient fall off a wall while the fixed one keeps decaying as .
The cliff is a little earlier than 16.6
One thing the paper's single number hides (measured). I swept in steps of 0.05 with one target logit and equal others, and recorded where F.cross_entropy's target gradient first became exactly zero:
| classes | fp32 | bf16 | fp64 |
|---|---|---|---|
| 2 | 16.65 | 5.55 | 36.75 |
| 3 | 15.95 | 5.55 | 36.05 |
| 10 | 14.45 | 5.55 | 35.25 |
| 100 | 16.0 | 5.6 | 34.75 |
| 1000 | 15.95 | 5.6 | 34.7 |
| 32000 | 15.95 | 5.55 | 34.7 |
With two classes it is the textbook . With more, the small terms are not summed before they meet the 1.0; each one is added to a running total near 1.0 and rounded on its own, so each is lost once it alone falls below half a step. With each term is , and the cliff moves to , exactly what PyTorch shows (reasoned from measured). Where it lands for larger depends on how the kernel vectorises the sum. bf16 does not move, because PyTorch's CPU kernel accumulates in fp32 and the cliff comes from rounding to bf16 afterwards. The paper's claim is unaffected; the cliff is, if anything, closer than it says.
The fix
Never add to 1. Take the max logit out of the sum entirely, compute the margin from the others with a log-sum-exp, and let a numerically stable softplus, , do the rest:
Because the target slot is the constant 0 rather than , reaches the loss only through the differences, so autodiff gives each non-target and the target exactly minus their sum. The paper ships it as nine lines of JAX. My PyTorch port of the hard-target version:
import torch, torch.nn.functional as F

def cross_entropy_fixed(z, t):
    z_t = z.gather(-1, t[..., None])                      # target logit
    is_t = F.one_hot(t, z.shape[-1]).bool()               # target mask
    others = (z - z_t).masked_fill(is_t, float("-inf"))   # exclude target from the sum
    m = -torch.logsumexp(others, -1)                      # logit margin
    return F.softplus(-m).mean()                          # = -log_softmax(z)_t
log_softmax gets the same treatment with the argmax standing in for . Across the whole sweep above, the port's gradient row summed to zero to within one rounding step in every format, and its target entry matched fp64 (measured).
Why a missing matters: Adam
A gradient of that should have been there is not obviously a problem. It becomes one because Adam does not care how big a gradient is. It divides the running mean of each parameter's gradient by the square root of the running mean of its square:
While , that normalised step is about 1 whatever the size of . So the paper's account of the slingshot (Thilak et al., 2022), the recurring loss spikes after a grokking network memorises its training set, runs like this (reported):
- After memorisation the margins grow, because the loss keeps pushing toward 1.
- Once a batch sits past the cliff, the target gradients are zero and what is left is the small, lopsided push from the non-targets. The gradient almost vanishes, and decays toward zero with it.
- Weight decay and that residual push drag a few examples back below the cliff. Their target gradients switch back on at about .
- Adam divides those restored gradients by a that has just decayed. The step is enormous, the loss spikes, resets, and the cycle starts again.
With the fixed loss, fades smoothly through the cliff, and decay together, and there is nothing to snap back.
The paper adds a second result that I find the more useful one. At a stationary point the update is zero, so . Once drops below the normalised step shrinks like , and since , weight decay stops the margin near
For PyTorch's default that is 18.42, just past fp32's 16.64 (reasoned). That is the whole reason the default triggers slingshots: training wants to settle at a margin the standard loss cannot represent. At the equilibrium is 16.12, below the cliff, and the paper notes standard cross-entropy then settles without spiking (reported). Barron's thread puts it as "the default eps=1e-8 happens to be juuust past where this bug kicks in for fp32 (this may be why some think a small eps is dangerous)."
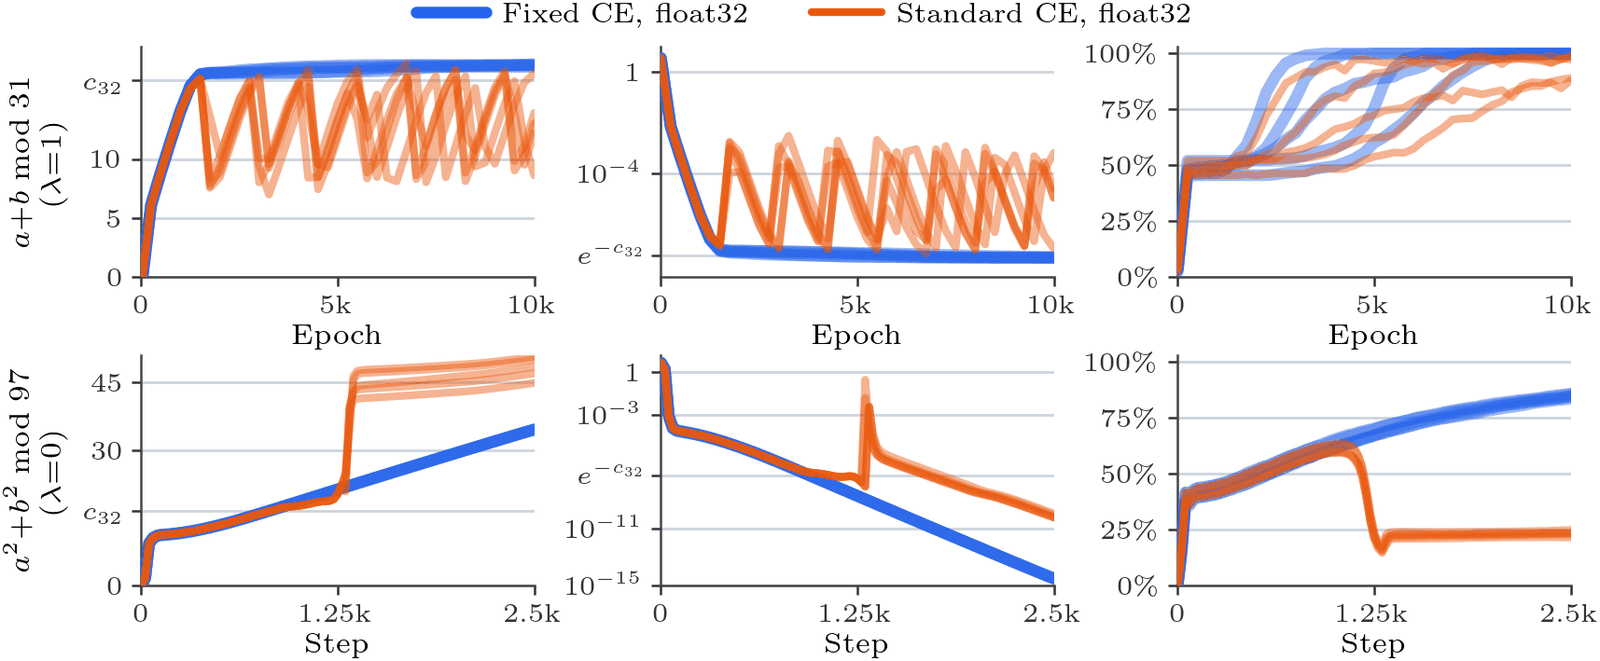
The paper's Table 1 puts numbers on the top row: on at , fp32 fixed cross-entropy reaches 100.0 ± 0.0% test accuracy against 94.3 ± 5.4% for standard (reported). The bottom row is the dramatic one: with no weight decay and , one spike at around step 1,250 drops standard cross-entropy from 61% to 23%, while the fixed loss continues to 85% (reported).
I ran the grokking experiment
The paper's Section 6 setup is a 1-layer, width-64 ReLU Transformer on with a 50% training split, full-batch AdamW at learning rate , betas 0.9 and 0.98, weight decay 1, , 10,000 epochs. The paper does not give head count, MLP width, initialisation or normalisation, so I chose: 4 heads, an MLP of width 256, PyTorch default initialisation, no LayerNorm, inputs a b =, read out at the last position. That leaves 480 training pairs and 481 held out. Each run is one process, one thread, nice -n 19, and took 2.5 to 11 minutes on the shared CPU, depending on load (measured). The only difference between a standard and a fixed run is the loss function: same seed, same split, same initialisation.
What I saw (measured, three seeds at learning rate ):
- The slingshots are real and the fix removes them. Standard cross-entropy produced 6, 6 and 6 slingshots in 10,000 epochs (a mean-margin drop of more than 3 within 100 epochs); the fixed loss produced 0, 0 and 0. The standard runs climb to a mean margin of 16.05 to 16.24, the moment a quarter to a third of training pairs are past the 16.64 cliff, and fall back to between 4.75 and 8.14.
- The fixed margin settles below the predicted equilibrium. It flattens at 16.51 to 16.83 by epoch 10,000, not at the 18.42 that predicts or the 17.9 the paper's Table 1 reports for fp32. My guess is that the approximation drops constants, such as the weight norm, that differ in my model (reasoned).
- Neither loss grokked in 10,000 epochs. Final test accuracy was 46.2, 47.6 and 50.7% for standard against 43.7, 46.2 and 48.6% for fixed. My model groks slower than the paper's, so 10,000 epochs is not enough to test the speed claim.
So I ran the same seeds at a learning rate of , which makes weight decay act three times faster per epoch (switch to it in the widget).
The result was the opposite of the paper's (measured, three seeds):
| learning rate | seed 0 | seed 1 | seed 2 |
|---|---|---|---|
| standard: slingshots | 7 | 7 | 7 |
| fixed: slingshots | 0 | 0 | 0 |
| standard: first epoch at 90% test | 5,890 | 5,470 | 4,090 |
| fixed: first epoch at 90% test | not reached | not reached | 4,680 |
| standard: test accuracy at 10,000 | 97.9% | 100.0% | 100.0% |
| fixed: test accuracy at 10,000 | 60.1% | 47.2% | 100.0% |
Standard cross-entropy grokked on all three seeds; the fixed loss grokked on one, later than standard did on the same seed, and on seed 0 it was just starting to climb when the run ended. In the standard runs, test accuracy climbs between slingshots: on seed 0 it goes from 50.5% at epoch 4,800, just after one, to 90.9% at epoch 6,000, just after the next. The fixed margins sat at 16.60 to 17.17 at the end, again under 18.42.
That is not what the paper reports, and I do not think it refutes it: three seeds of one architecture I had to partly guess, against five seeds and four benchmarks. The paper itself says that whether spikes help or hurt depends on how the weight norm is controlled, and that with LayerNorm and no weight decay each spike "acts as an accidental learning-rate decay" (reported). My model has weight decay and no LayerNorm, the case where the paper says spikes only hurt. What my runs do support without reservation is the mechanism: every sawtooth tops out just as a quarter or more of the training pairs cross the cliff, and the fixed loss has no sawtooth at all.
Bug two: Softmax Cancellation
The second bug lives in distillation, where the target is itself a softmax, of teacher logits. The standard code computes and separately, rounds both to probabilities, and subtracts. When the student is close to the teacher, that is the subtraction of two nearly equal numbers, and the small logit gap is gone before the subtraction happens. Worse, comes from softmax in the forward pass while comes from exp(log_softmax) in the backward pass, two different sequences of roundings, so even at , where the true gradient is zero, they do not cancel (reported).
The fix computes from directly, in log space, with expm1 and log1p so nothing is ever added to or subtracted from 1:
with and , a fallback to when , and a final projection so the row sums to zero.
My PyTorch reproduction of the paper's example, and in fp32 (measured). In fp32 that perturbation rounds to , so the exact gradient is of those rounded inputs:
exact (fp64 of the rounded inputs)  [-4.5955e-08,  4.1442e-08,  4.5131e-09]
fp32 standard (PyTorch)             [-5.9605e-08,  4.4703e-08,  7.4506e-09]  sum=-7.451e-09
fp32 fixed                          [-4.5955e-08,  4.1442e-08,  4.5131e-09]  sum= 1.776e-15
PyTorch's standard gradient is wrong by 30% in the first entry and 65% in the third. The paper's JAX run of the same thing is wrong differently, [-5.960e-8, 1.452e-8, -1.123e-9], with the third sign flipped (reported). Different frameworks, different rounding sequences, different wrong answers, which is the point.
Then the clean test, suggested by more than one reply to Barron's thread: set the student equal to the teacher, where the gradient must be zero. 64 rows of 1,000 random logits each (measured):
| format | standard: max abs gradient | standard: entries non-zero | fixed: max abs gradient |
|---|---|---|---|
| fp64 | 6.985e-16 | 95.4% | 0 |
| fp32 | 2.778e-07 | 96.3% | 0 |
| bf16 | 2.747e-03 | 100.0% | 0 |
That residual is harmless in plain SGD. Under Adam it is not, for the same reason as before: any gradient larger than becomes a full-sized step. The paper initialises a student with its teacher's weights on and runs 2,000 Adam steps: the fp64 residual of about sits below and nothing moves, fp32's residual causes an initial KL spike and a floor near , and bf16's drives the student away from the teacher and costs test accuracy, while the fixed loss stays at KL 0 and 100% in every format (reported, Section 7). I did not re-run that experiment.
Who should care
The paper is candid that "the extreme margins and near-zero student–teacher gaps probed by our experiments are uncommon in standard large-scale training" (reported). I would not expect language-model pretraining over a 100,000-token vocabulary to sit at a margin of 16 on most tokens (reasoned). But four places do reach it.
- bf16 losses. The bf16 cliff is a margin of 5.55, a probability of about 0.996 on the right answer (reasoned). Most training code upcasts logits to fp32 before the loss for this reason among others; code that does not is collapsing on every easy token.
- Small-output problems trained long. Grokking, classifiers with a few classes, anything past memorisation with weight decay and default .
- Distillation from a close teacher, and KL penalties that start the policy as a copy of the reference, which is how most RL fine-tuning begins. One reply points at continual-learning penalties that start the new model as an exact copy of the old one.
- Attention. Attention is a softmax too. A reply to the thread from the authors of Broken Symmetry in BF16 Attention argues the same broken zero-sum shows up in FlashAttention's bf16 backward. That is their claim; I have not checked it.
Prior fixes treated symptoms: Liu et al. project the gradient to zero sum, StableMax (Prieto et al., 2025) replaces the exponential, and others cast to fp64. The paper's Table 1 finds zero-sum projection stalls the margin near 18 and drops test accuracy below 50% at , and StableMax lets margins run to about (reported). Liu replied that their main contribution is the mechanism, "Numerical Feature Inflation", and that the projection was a causal test.
What the fix costs: an argmax, a masked log-sum-exp and a softplus instead of one fused kernel. The paper says it runs "without meaningful slowdown" (reported). I did not benchmark it, and a reply asking about fused vocabulary-scale kernels has no public answer yet. My unfused port allocates a few extra temporaries, which at a large vocabulary is the memory a fused cross-entropy exists to avoid.
Two notes on provenance. Barron writes that the bug was "first found and fixed by Gemini Flash 3.7", that most experiments were run by Flash 3.8 and the first draft written by a Gemini model before he rewrote it (reported, from his thread); a reply points out the paper itself does not say so. And no code repository is published: the code is the listings on the project page, which is what I ported.
The takeaway
The bug is one addition: . Everything else follows from where floats are dense and where they are sparse. If a quantity you care about is tiny, compute it directly; never compute it as the difference between 1 and something close to 1. The same lesson is why log1p and expm1 exist, and it is the whole of both fixes. For a different, older problem with the same output layer, see the softmax bottleneck; for softmax inside attention, the attention explainer; for training natively in low precision, A.X-K2; for loss spikes caught by an optimizer that watches itself, reactive optimizers; and for distillation measured on a reasoning model, Inkling-Small.