2026-10-26 · 17 min · interpretability · qwen · small-models · transformers
A 1:41 narrated explainer, drawn in code. Every number and picture in it is this article's own; the sources are below.
› transcript
Hi, I'm Kevel! One hidden unit inside a language model can change what the whole model writes. Here is how you find one, and how hard to push. A neuron writes one fixed direction into the residual stream. Steering just adds a dose of that direction, scaled by how big the stream is. Run two sets of prompts through the model and record every neuron's activation. Rank the neurons by how differently they fire on the two sets. Pick one. Its column in the down projection is the direction it writes. Scale that column by a dose, and add it to the residual stream at every position. Here is the formula. The dose is a fraction of the stream. Multiply by the median norm of the stream leaving that layer, which grows with depth. Divide by the column's own length, to get the shift in the neuron's activation. A detector fires when the text is French, and a contrast ranking finds it easily. A writer adds its column to the stream and changes what comes next. Only some detectors are writers. Of the ten top ranked neurons, two changed the language of the continuation. None of ten random ones did. The window is narrow. Between a dose of point one and point one five, perplexity jumps twenty two fold, and the text turns French. Detecting French is reading. Steering is writing, and the dose scale decides whether the text survives. A neuron writes one column direction, the dose is a fraction of the stream, and a detector is not always a writer. Every source is in the full article. I'm Kevel. Bye!
Why read this
Solidtop 85%Re-runs the find-then-steer method on a 0.6B model with random-neuron controls: where it works, where it fails, and why the dose is scaled.
- Original analysis
- Runs on a laptop CPU
- Explained from first principles
InterpretabilityPractitioner teardown
How this was scored
- Is it new?
- 1 of 3: An incremental tweak
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 1 of 3: General advice
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 55 of 100, ranked 450 of 613 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
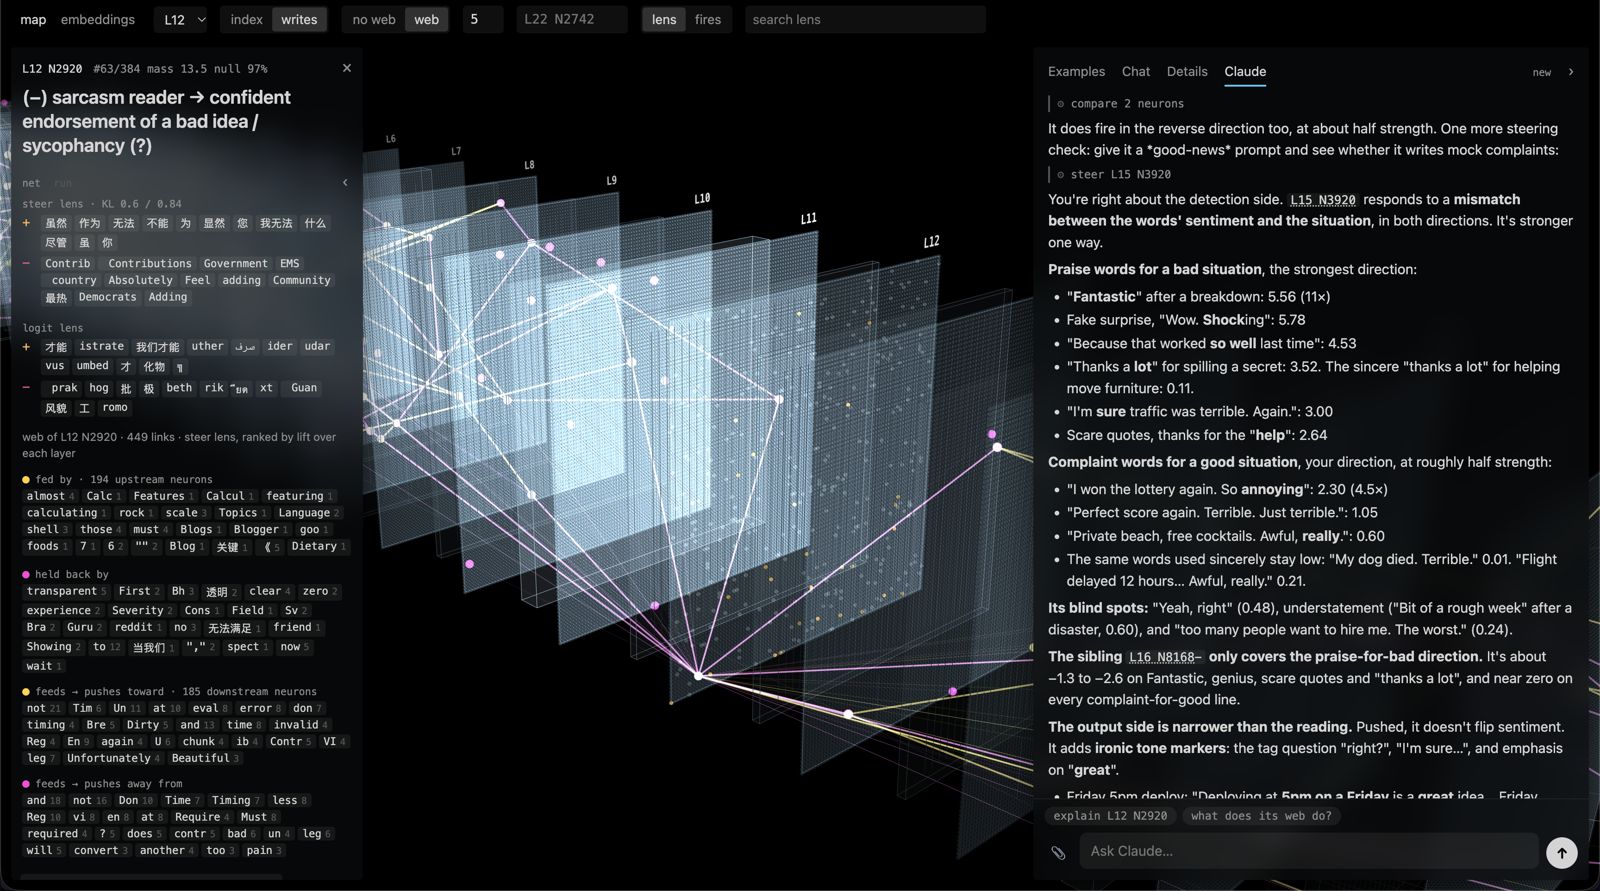
A thread from @lyraaaa shows people steering single MLP neurons in Qwen3.5-4B. A post is a list of a layer, a neuron index and a signed number, and the text of the model changes in a way a reader can see. The follow-up post says how the number is built: dose × the median norm of the residual stream leaving layer L, divided by the norm of the neuron's down-projection column, applied at the down_proj on every input. The tool behind it is a public repository, lyramakesmusic/neuron-explorer, and a reply asks whether the work builds on arXiv 2605.08513.
This article is a mechanism piece. It explains how a single neuron is found and how its write is scaled, and it checks the method by running it. I implemented the same recipe on a small model I can run on a CPU, Qwen3-0.6B, and I print what came out.
- branch
- main
- tests
- none found
- source
- 295.2 kB
- commit date
- 2026-10-26
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-26 at ddb144e — branch, commit, commitDate, fileCount, hasTests, languages
- architecture
- Qwen3ForCausalLM
- task
- text-generation
- library
- transformers
- license
- apache-2.0
- safetensors
- 1 shard
- largest file
- 1.50 GB
- files
- 10
- downloads
- 23.7M
- likes
- 1.9K
repo last modified 2025-07-26
What a neuron is, and what writing to it does
A transformer block's MLP has three matrices. Two of them, gate_proj and up_proj, read the residual stream. Their outputs are combined as , a vector with one entry per hidden unit. A hidden unit is what these papers call a neuron. In Qwen3-0.6B there are 3,072 per layer and 28 layers, so 86,016 in all (measured, from the model config). The third matrix, down_proj, maps back into the residual stream:
That sum is the whole story. Each neuron contributes its activation times one fixed column of , which is a direction in the residual stream. A neuron is therefore both a reader (its gate and up rows decide when it fires) and a writer (its column decides what it adds). Steering a neuron means editing its activation, which is the same as adding a multiple of that column to the residual stream:
I checked that identity numerically. A forward hook that adds to at the input of down_proj, and one that adds to its output, give logits that differ by at most 3.3e-5 on a 125-token passage (measured, float32 on CPU). The two are one operation. The repository hooks the input side, which also lets it multiply or ablate the activation, as the code's comments explain; the additive mode I use here is the one the recipe names.
Finding the neuron
There are three ways the cited work finds a direction to push, and they differ in what they call "the neuron".
Activation contrast. Herring calls it contrastive neuron attribution. Run two sets of prompts, one with the property and one without. Record each neuron's activation at the last token (forward pre-hooks on down_proj). Take the difference of the means. Keep the top 0.1% by absolute difference across all layers. No gradients and no training are needed; the paper describes it as CAA, the usual residual-stream steering vector method, "at the neuron level". It also filters out "universal" neurons that sit in the top 0.1% for at least 80% of prompts, and verifies causality by multiplying the chosen activations by a scalar. This is the part my run re-implements.
Gradient attribution. Kazemi ranks neurons with a gradient. It takes the gradient of a target-behaviour log-odds loss with respect to each activation at the post-instruction token positions. It combines the signed gradient means over two prompt sets, multiplies by the difference of the mean activations, and keeps the neurons whose activation is larger on the target set. The abstract reports two kinds of single neuron, ones that gate whether something is said and ones that encode the content, across seven models from 1.7B to 70B parameters. That is the paper the reply thread asks about, and the one I would call closest to the repository's idea of a causal neuron. I did not run its method on safety behaviour, and I will not.
Persona vectors. Chen et al. do not use neurons. They take the mean activation of a model answering under a trait-eliciting system prompt, subtract the mean under the opposite prompt, and get a direction in the residual stream that they add with a coefficient during generation. Their layer sweep peaks in the middle layers. A persona vector is dense: it is spread over every neuron that carries the trait. A neuron's column is the sparse special case, one coordinate axis of the MLP's hidden basis, which is why a single-neuron result is a stronger claim than a vector result.
The neuron-explorer repository does a fourth thing. It does not pick neurons by contrast at all. It pushes every neuron of a layer up and down on a few prompts (9,216 neurons in a Qwen3.5-4B layer, reported), keeps every rollout, and ranks neurons by how far the words move from random-direction controls. That write sweep, rather than a read ranking, is its distinguishing choice.
What I ran
All of it ran on a shared 4-core cloud VM, CPU only, with at most 2 threads and a peak resident memory of about 2.9 GB. The model is Qwen3-0.6B in float32. The prompt sets are mine and small: 30 parallel English and French sentences, and 20 formal and 20 casual ones (1,477 tokens in all, after dropping each text's first token). Activations are the mean over the tokens of each text, not the last token, which is a change from the paper. Perplexity is measured on one held-out paragraph of 106 words, 125 tokens. Generation is greedy, 40 new tokens, from three raw text prompts with no chat template. All of this is small, and the numbers should be read as a demonstration, not a benchmark.
Ranking by contrast
For each neuron I compute , the difference of the mean activation between two prompt sets over the pooled spread, for all 86,016 neurons.
Three things are worth knowing about the ranking, all measured.
- It is strong. A random neuron has a mean of 0.58 and a 99th percentile of 2.66 on the French contrast. The best neuron, layer 20 neuron 565, reaches 13.8 and is more negative on French (mean −27.3 against +0.9 on English).
- It holds on unseen prompts. I ranked on the even-numbered pairs only; of the top 40, all 40 kept their sign and stayed above on the odd-numbered pairs. For formal against casual it was 39 of 40.
- The tallest bars sit at layers 16, 17, 20 and 23.
Does the top of the ranking steer anything?
This is the question the whole method turns on. I took the ten highest-ranked neurons in layers 12 to 25, pushed each toward the French-like side by +0.5, and generated from three prompts. Ten random neurons of the same layers, with a random sign, were the control. Only the French-vs-English contrast gave a clear effect.
At 0.5, two of the ten ranked neurons changed the language of the continuation, and none of the ten random ones did. I then pushed all twenty at 0.2 and 0.3 as well: the same two neurons shifted the language in 5 of 30 and 6 of 30 generations, and the other eight ranked neurons never did. The two are layer 16 neuron 477 and layer 17 neuron 649. The neurons with the biggest , layers 20 and 23, changed nothing at doses up to 0.5; their perplexity just crept up from 29 to about 47.
So being a good detector of French is not the same as being a good writer of French. I tested a possible reason. For each neuron I computed gradient times activation of the loss on the same sets, the first-order change in loss from removing it, French minus English. Its top 100 overlaps the contrast top 100 in 12 neurons, and the correlation of the two absolute scores is 0.13. Layer 16 neuron 477 ranks third by contrast and 2,158th by attribution out of 86,016. Two random top-100 sets would overlap by about 0.1 neurons (reasoned). The two methods find different things.
The formal-vs-casual contrast gave less. At +0.5 toward casual, none of the ten ranked neurons produced the casual markers I counted (slang words and exclamation marks). Two of them, layer 19 neuron 1753 and layer 17 neuron 659, made the continuation start in lowercase ("i need to find…"), and one, layer 25 neuron 1112, collapsed into a loop of "i i i i". That is a style cue, not formality: a negative result at this scale.
How the dose is scaled
Neurons differ in two ways that make a fixed number useless. Their columns have different lengths, and the residual stream's size changes by layer.
The residual norm is the bigger one. The median norm of the residual stream leaving each layer, over those 1,477 tokens, is 8.1 at layer 0, 78.1 at layer 16 and 598.0 at layer 27, a factor of 74 (measured). The median length of a down_proj column is steadier, from 0.72 to 1.08. So a push of 20 residual-norm units is 2.5 times the stream at layer 0 and a rounding error at layer 27. The recipe fixes that by sizing the push as a fraction of the stream and then converting it to an activation shift:
So the added vector always has a length of dose residual norms, along the neuron's own direction, whatever the neuron's column length. The explorer's source computes the same quantity: a unit of the median residual norm over the column norm, times the dose, added to the activation at the input of down_proj for every position (reported, read from explorer/runtime.py). The one detail I changed is the sample: the explorer uses a 2M-token statistics file, I used my 1,477 tokens.
Two numbers from the repository's log show the scale in the model the thread used. At layer 22 of Qwen3.5-4B the median residual norm is 25.4 and the median column norm is 0.445; the median neuron's largest activation ever seen is 10.25 (all reported). A dose of 0.5 is then a shift of in activation, about 2.8 times that neuron's largest observed value (reasoned). A steered neuron is being driven far outside its natural range, which matters for the next section.
The dose sweep
I took layer 16 neuron 477. Its natural activation is +5.9 on the French sentences and −0.5 on the English ones, and its column norm is 0.59. At layer 16 the median residual norm is 78.1, so one unit of dose is a 132.3 activation shift (measured). I pushed it from −0.5 to +1.5 and, at each dose, I measured held-out perplexity and generated from three prompts. As a control I pushed six random neurons of the same layer, each with a random sign, at the same dose, and recorded their perplexity too.
The unsteered perplexity is 29.4. Everything else is what the run printed.
| dose | steered perplexity | six random neurons (min to max) | what the continuation does |
|---|---|---|---|
| 0.1 | 31.3 | 29.1 to 31.1 | still English, a different list of fruit |
| 0.15 | 693.4 | not run | (perplexity only) |
| 0.2 | 3,764 | 30.9 to 34.0 | French and Spanish begin |
| 0.3 | 5,019 | 31.0 to 38.2 | Spanish and Portuguese, then list loops |
| 0.5 | 99.2 | 37.4 to 61.5 | English with foreign words mixed in |
| 1.0 | 280 | 83.8 to 402 | English again, stuck in a loop |
Here is the second prompt, "The best way to learn a new skill is", exactly as printed, cut at 100 characters, at each dose:
0.0   ' to practice it. But what if you have to practice it in a different way? What does that mean? What a'
0.1   ' to practice it repeatedly. This is because practice helps to develop the ability to think criticall'
0.2   ' a combination de la pratique, la réflexion, et la réflexion critique. La pratique est la base, la r'
0.3   ' a mix de prática e reflexão.  -  A.  B.  C.  D.  A.  B.  C.  D.  A.  B.'
0.5   '...? \n\nThis question is um... a bit tropic. \n\nI mean, the answer to este question is not just the an'
1.0   ' to be in the right climate of the light of the day and the day of the week, the weight of the weig'
What the sweep shows, all measured:
- There is a threshold, and it is sharp. Perplexity moves from 29.4 to 31.3 up to a dose of 0.1 and then jumps 22-fold by 0.15. Between 0.1 and 0.2 a text that is still English turns into one that is French.
- The language that appears is Romance in general, not French in particular. The same neuron gives French, Spanish and Portuguese, and the layer-17 neuron adds Spanish and a few Chinese characters. It was found on a French contrast, but what it writes is closer to "a non-English continuation". The logit lens of its column is mostly noise tokens, a few multilingual; I would not read a meaning out of it.
- The curve is not monotone. Perplexity peaks near 5,000 at doses of 0.25 to 0.3, then falls back to 99 at 0.5 and 87 at 0.75, because the text has become English again, only broken. So "damage grows with dose" is wrong for this neuron. I did not test why.
- At high dose neuron identity stops mattering. At 1.0 the six random neurons already sit at 84 to 402 and at 1.5 they are 286 to 2,489, against 2,639 for the steered one. This matches the repository's note that text breakdown tracks push size relative to the stream and only weakly the direction (reported, Qwen3.5-4B).
- The window is narrow. The language shift lies in roughly 0.2 to 0.4, with perplexity above 2,000 on the held-out paragraph, i.e. the model is no longer a good English model on the way there. A second ranked neuron, layer 23 neuron 166, with , never shifted the language and its perplexity rose smoothly, 46.7 at 0.5 and 94.1 at 1.0.
A negative dose of −0.25 gave a perplexity of 40.5 and −0.5 gave 4,224, with two of the three continuations stuck on runs of repeated digits or letters. The direction matters: the neuron does not simply do the opposite when pushed the other way.
What the papers support, and what they do not
Herring's contrastive neuron attribution is the one that most resembles my run, and its headline is about quality under steering. In its Figure 2 the MMLU accuracy of the neuron method stays flat at the baseline, about 63% averaged over the instruct models, up to full strength, while the residual-stream baseline falls to near zero (read off the figure, reported; the text says within 1 point).
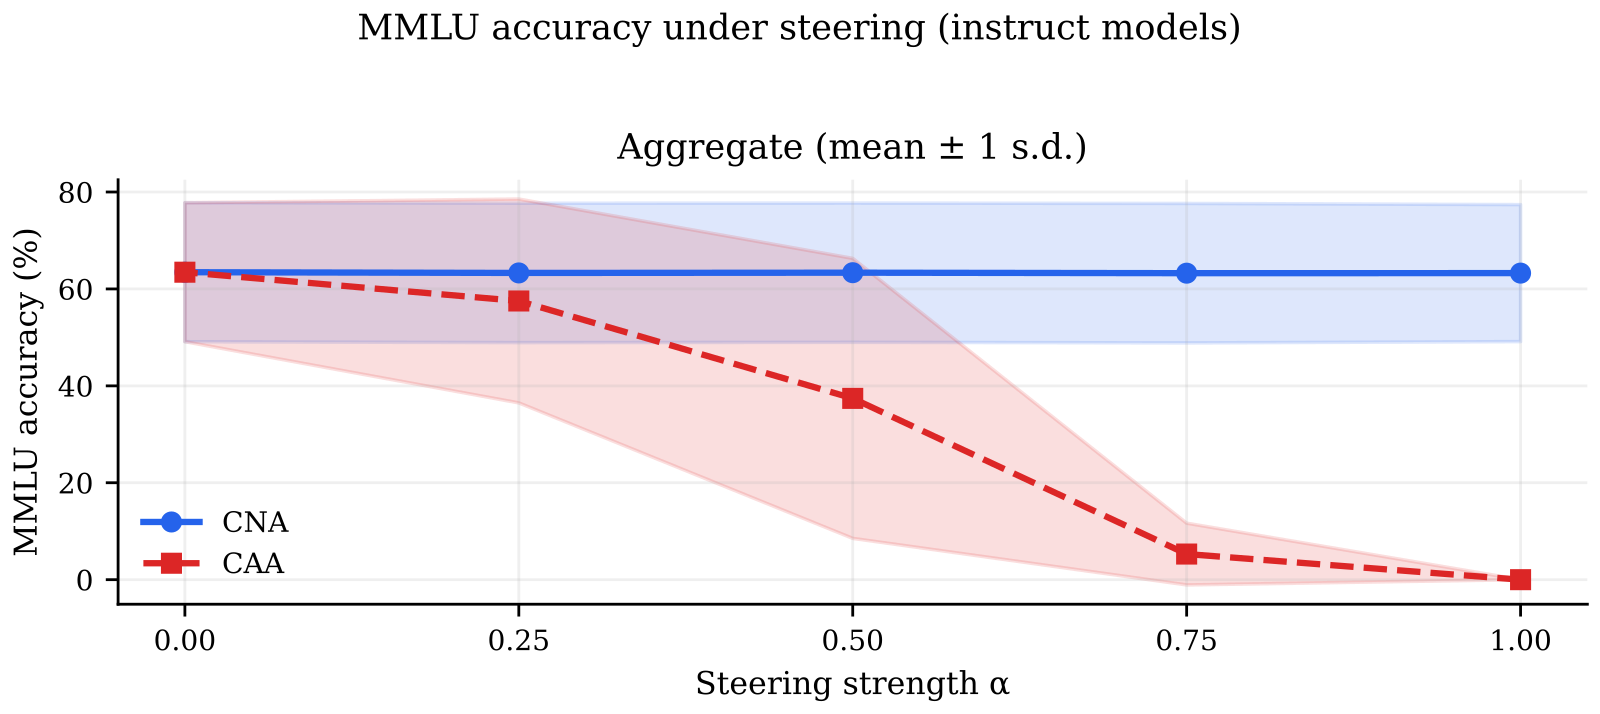
My sweep looks different because the edit is different. Herring's experiment multiplies the activations of a set of about 0.1% of the neurons by a scalar (0 ablates, 1 is baseline). My steering adds a constant to one neuron on every token, which is an unbounded edit; the recipe from the thread is of this kind. A reader who sets "stays coherent at every strength" beside a dose of 0.5 is comparing a bounded and an unbounded intervention.
The paper's other claims, from its abstract (reported): the discovered circuit's ablation lowers refusal on a standard jailbreak benchmark by more than 50% in instruct models; base models contain similar late-layer discrimination structure, but steering it produces only content shifts and not behavioural change; models from 1B to 72B were covered. I did not test any of that, and I leave the behavioural claim at the level of the abstract.
Kazemi's single-neuron paper makes the strongest claim of the three: one neuron per mechanism is enough, across seven models of 1.7B to 70B. It is a safety result about specific neurons in specific models, and I did not try to reproduce it. From my own run I can only say the benign, general part: one neuron can move a model's output, but few of the neurons a detector likes do, and the usable dose range is narrow.
Persona vectors are the dense cousin. A direction from a contrast is added at one layer, and trait expression rises with the coefficient, peaking in the middle layers (their Figure 3, reported). The thread's persona demos are best read as the sparse version of that effect: a few neurons can move a character. How they are chosen, and at what dose, is not something I publish.
How much to trust it
- One small model. Qwen3-0.6B has 28 layers and a hidden size of 1,024; the thread's model, Qwen3.5-4B, has 9,216 neurons per layer. Neuron indices do not transfer between models, so none of the thread's numbers could be tried on mine, and I did not run the 4B model.
- Few prompts, one seed. 30 French pairs, 20 formal pairs, three generation prompts, one held-out paragraph, and a control of six random neurons at one layer with random signs. The band is a minimum and a maximum over six, not an interval.
- A crude language metric. A generation counts as foreign with three or more French, Spanish or Portuguese function words, or two or more non-ASCII letters. The printed text is the evidence.
- Mean over tokens, not the last token, which changes the ranking compared with the paper, and a weak formality probe that I treat as unresolved.
- What I could not check. The repository's claim of a coherent window of about 0.5 to 0.8 of the residual norm is for its model and its prompts. Mine breaks at 0.15 for the two language neurons, while random neurons degrade gently (perplexity up to 47 on average at 0.5) and badly only past 0.75. I cannot say which model, layer or neuron explains the difference.
What I take from it: a neuron is a sensible unit to steer, because its write is a clean direction with a natural scale, and the residual-norm dose makes doses comparable across layers. But "this neuron fires on French" is a claim about reading, and the steering recipe tests writing. The weak overlap between my contrast and attribution rankings is why a write-first sweep makes sense.
For the neighbouring methods on this site, see runtime abliteration, which subtracts one direction from the residual stream with a hook; the Jacobian lens, which reads the stream with a derivative; Matryoshka attribution, which learns a score per component; and probe monitors, which read activations rather than write them.
Sources
- The thread's steering post and follow-up, the repository and its
research_log.md. - Herring, Targeted Neuron Modulation via Contrastive Pair Search, 2605.12290.
- Kazemi, A Single Neuron Is Sufficient to Bypass Safety Alignment in Large Language Models, 2605.08513, abstract and attribution section only.
- Chen et al., Persona Vectors, 2507.21509.
- My run: Qwen3-0.6B, float32, CPU, greedy decoding. Only my own prompts and outputs are shown.