2026-10-27 · 17 min · motion-generation · robotics · humanoid · nvidia · transformers

Why read this
Notabletop 60%Licence read in full; parameters, codebooks and pass count taken from headers and exporter code; paper's sizes checked against the files. Inference not run.
- Original analysis
- Runs on a consumer GPU
- A new technique
Robotics & embodiedMixed licencesPractitioner model
How this was scored
- Is it new?
- 2 of 3: A real new idea, method or capability
- Can I trust it?
- 2 of 3: Measures key facts from files, code or configs
- Can I run it?
- 2 of 3: Open code or weights with real limits
- Will I understand it?
- 2 of 3: Mechanism from first principles with figures
- Can I act on it?
- 2 of 3: A concrete recipe, numbers or comparison
- Will it last?
- 1 of 3: Relevant for months
- Does it affect many?
- 1 of 3: A specialist community
- Only here?
- 2 of 3: A teardown or measurement few others did
Score 63 of 100, ranked 265 of 621 rated articles. Each question is answered 0–3 by hand, and a 3 is rare. How articles are scored
MotionBricks is NVIDIA's motion generator for characters and humanoid robots. You give it the last few poses of a body and the poses you want it to reach, and it writes the movement in between. The announcement thread (@alvarobartt) points at the weights on Hugging Face, the project page shows the demos, and the paper is arXiv:2604.24833, now in ACM Transactions on Graphics.
This article is a read of the release rather than a review of the animation. I read the licence text, the model cards, the checkpoint headers and the exporter code, counted what could be counted, and timed what could be timed on a CPU. Every claim carries one of three labels. Measured means I computed it from a file or ran it. Reported means it comes from NVIDIA's cards or paper and I did not check it. Reasoned means arithmetic or inference from the first two. I did not run the model's inference, and I say where that matters.
- license
- Apache-2.0
- branch
- main
- tests
- 46 files
- source
- 1.5 MB
- commit date
- 2026-10-23
by size of tracked source at this commit, file counts in brackets; docs, data and vendored trees excluded
local clone, 2026-10-27 at 54fc563 — branch, commit, commitDate, fileCount, hasTests, languages, license, licenseFile, shallow, testFileCount
shallow clone: counts describe the pinned tree, not the history
- task
- robotics
- library
- pytorch
- safetensors
- 6 shards
- largest file
- 546.4 MB
- files
- 62
- downloads
- 0
- likes
- 55
repo last modified 2026-10-23
The licence, stated exactly
The Hugging Face metadata has no license field. I fetched the model's API record and the cardData block holds only a library name and tags (measured, 27 October 2026). So the licence is in the card's text, and it is split four ways. Reported, from the repository card:
- The weights are under the NVIDIA Open Model Agreement. The card says it "permits commercial use and redistribution of modified models, subject to the agreement's terms".
- The software is Apache 2.0. The repository's LICENSE file says the code is Apache-2.0 and the documentation, skills and assets are CC-BY-4.0.
- The motion samples (the bundled Bones-derived BVH and G1 CSV clips) are under the NVIDIA Sample Data Evaluation License, for internal evaluation and testing of NVIDIA technologies. They are not in the weights repository.
- Robot assets and third-party dependencies keep their own licences.
I also read the Agreement itself, release date 2 April 2026, on NVIDIA's site (measured). Its opening says the Works are "commercially usable" and that you are "free to create and distribute Derivative Works", and that NVIDIA claims no ownership of outputs. The grant is perpetual, worldwide, royalty-free and irrevocable. The conditions are modest. If you redistribute, you pass on a copy of the licence and keep the notices, and if the work ships a NOTICE file your derivative must carry the line "Licensed by NVIDIA Corporation under the NVIDIA Open Model Agreement." The licence ends for you if you sue anyone claiming the Work or its output infringes a patent or copyright. Trademarks are not granted, and there is no warranty.
So the weights are not gated (the API says gated: false, measured) and not non-commercial. They are also not Apache 2.0 or MIT, and the card says "subject to the agreement's terms", so a company shipping them should read the Agreement rather than this paragraph. I am not a lawyer. The sample clips are the one part that stays evaluation-only, and a game that wants to ship Bones motion data needs a separate arrangement.
What you get
The repository has two families of weights, g1/ for the Unitree G1 robot and soma/ for a human skeleton, and each has three safetensors files. The three files are not equal: only the pose predictor is about 546 MB. Sizes from the repository's manifests (measured):
| Component | G1 | SOMA |
|---|---|---|
| Tokenizer (VQ-VAE) | 95.2 MB | 93.4 MB |
| Pose predictor | 546.4 MB | 546.1 MB |
| Root predictor | 136.5 MB | 161.7 MB |
| Training step | 2,000,000 | 1,500,000 |
That is 778 MB for G1 and 801 MB for SOMA, 1.58 GB in all. The files are float32 with the skeleton arrays, normalisation statistics and a config beside each. The README is plain that these are not Transformers from_pretrained models, that there is no training pipeline or training data, and that the optimizer state is missing, so you can initialise a fine-tune but not resume the run. The software repository also ships ONNX exports of both families (G1 float32 is 734 MB, measured from the LFS pointer), and the card says you do not need the safetensors to run the demos.
The pipeline
The paper's Figure 2 draws the whole system in four stages.
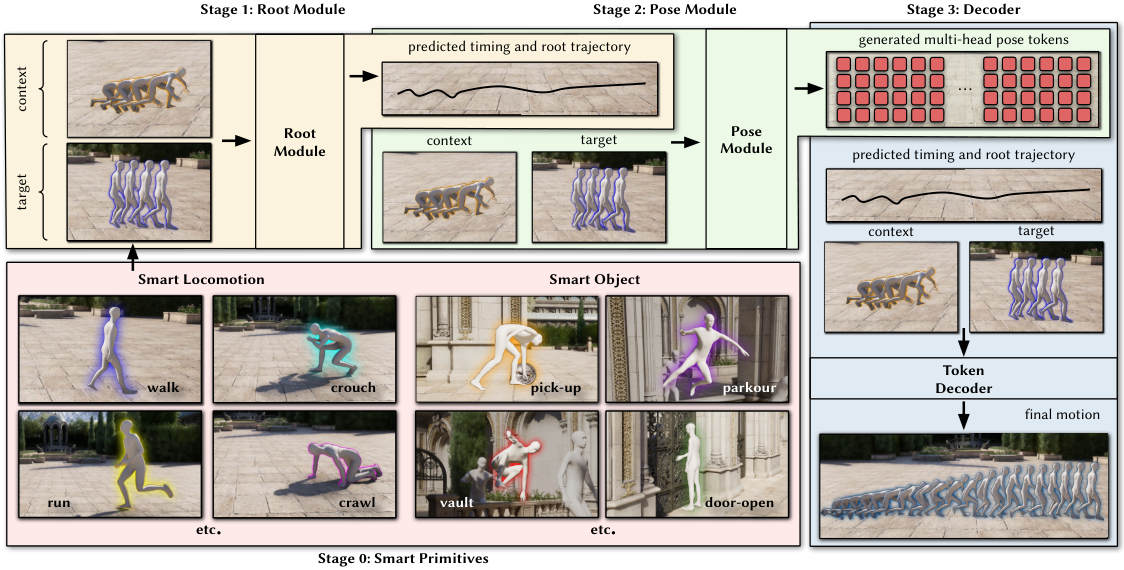
Stage 0 is application code. The paper calls it a smart primitive: a walk command or a ledge to vault turns into one to four target keyframes. The model never sees a command, only poses and masks. Stages 1 to 3 are the three checkpoints. Reading the G1 card and the exporter (tools/onnx/models/g1/), the interface is this (reported by the card, measured where I checked the tensor shapes):
- Inputs: four context poses and up to four target poses, each 36 numbers (root position, root quaternion, 29 joint angles), plus three masks saying which of the eight slots carry a root position, a root velocity and a body pose, plus 11 flags for which durations are allowed.
- Duration: the clip is 6 to 16 tokens, and one token is four frames at 30 Hz. That is 24 to 64 frames, 0.8 to 2.1 seconds. The root predictor picks the length.
- Outputs: up to 64 frames of joint coordinates, four foot-contact flags per frame, and the chosen token count.
Longer motion is repeated generation. The last output becomes the next context, and the paper triggers a replan when the command changes or the buffer runs low, at 10 Hz on the robot (reported).
What is in the files
The released tensors let me count every parameter. I read the header of each file with an HTTP range request, which is the first 8 bytes for the length and then the JSON, and multiplied the shapes. Nothing but headers and two tiny codebook tensors was downloaded.
The counts match the cards. G1 comes to 194,506,928 parameters (23,795,822 tokenizer, 136,588,273 pose, 34,122,833 root) and SOMA to 200,297,280. Three things stand out.
The pose predictor is a plain transformer. Of its 136.6 million parameters, 134.4 million (98.4%) are in 16 layers of width 1024, with 16 heads and feed-forward width 2048 (measured, from in_proj_weight of shape 3072 by 1024 and linear1 of 2048 by 1024). The exporter builds them with nn.TransformerEncoderLayer at its defaults, so post-norm and ReLU (measured, from the code). There is nothing exotic in it: no rotary embedding, no mixture of experts, a learned position table of 16 entries because there are never more than 16 positions.
The paper's sizes do not match the files. The paper says the pose module has 150 million parameters and the root module 50 million, and the tokenizer has "1024 channels" (reported). The released pose predictor has 136.6 and 136.5 million, the root predictors 34.1 million (G1) and 40.4 million (SOMA), and the tokenizer's convolutions are 512 wide (measured). The tokenizer total, 23.5 million in the paper and 23.8 million here, agrees, so the "1024 channels" is probably a loose description, but I cannot tell from the files. The released networks may be a slightly different configuration from the ones the paper's tables used. The G1 card says its weights come from the earlier GR00T Whole-Body Control preview, trained from scratch on the same motion corpus; the paper's benchmark models were trained separately (reported).
The root predictor is not the same in both families. G1's has 3 shared plus 3 root-only transformer layers at width 512. SOMA's has 6 shared plus 2 root-only (measured, from the layer indices), and that is where its extra 6.3 million parameters sit. The paper describes the root module as one design.
A codebook of ten, or sixteen
The tokenizer is a vector-quantised autoencoder with convolutions, and its codebook is the one design choice the paper leans on. Instead of one large codebook, each token is several small codes, one per head, concatenated. The G1 file's codebook tensor has shape [8, 10, 32] (measured): 8 heads, 10 codes each, 32 numbers per code, which concatenate to the 256 values per token that the card lists. The exporter's rule is codes per head = round(2^(log2(nb_code) / heads)), and the config says nb_code: 100000000, so 10^8 over 8 heads gives 10 (measured, config and code).
The SOMA tokenizer is not the same. Its codebook is [5, 16, 32]: 5 heads of 16 codes and a nb_code of 1,048,576, which is 16^5 (measured). I did not expect that. The paper's ablation recommends "128 to 256" per head and about a fixed total, as I read the extracted text (reported), and neither release is near it. I cannot say why; the cards do not discuss it, and the paper's formulas did not survive my text extraction.
The pose predictor's head confirms the layout. Its token embedding table has 88 rows of 32, which is 8 heads times 11 (ten codes plus a mask code), and its output layer is 1024 by 80, which is 8 heads times 10 logits (measured). During generation every position starts as all masks.
The shares come from cluster_size, the running count the quantiser keeps for its moving-average codebook update. It is a proxy for how often each code was chosen near the end of training, not a count over the corpus. By that proxy, no head is flat. G1's first head has one code at 0.2% and another at 19%, and the summed entropy is 23.1 bits per token against a maximum of 26.6 (measured). SOMA uses 18.2 of 20 bits. A head that leaves codes nearly unused is not a bug, and the paper argues the multi-head form degrades gracefully when one head is mispredicted (reported). I did not test that.
A token covers four frames, so a one-second clip is about 7.5 tokens and about 60 code predictions for G1. That is the whole prediction problem the transformer faces. It chooses a few dozen small integers, conditioned on the root path and on the poses you pinned.
One pass, not an iteration
The paper describes the pose module as masked-token modelling that "iteratively predicts the pose tokens based on confidence", and adds that "a single forward pass at inference typically produces high-quality motion" (reported). The released exporter settles which one ships. tools/onnx/models/g1/model.py sets "num_inference_step": 1 and "pose_token_sampling_use_argmax": True, and the sampling loop in inference.py raises an error if argmax is off (measured, code). So the exported model makes one pass of the 16-layer transformer, takes the argmax code in every head, and decodes. The cosine schedule of masks that I found in the loop matters only if you raise the step count, which the release does not expose.
I find this the most useful fact for anyone planning to build on it. The generator is deterministic. There is no sampling temperature and no seed. Two requests with the same inputs return the same clip, and variety has to come from the targets you choose, from the allowed-duration flags, or from the numerical differences the card warns about: "Mixed FP16 and FP32 can produce different motion, because rounding affects the choice of motion tokens."
The root predictor works the same way. It reads the eight boundary frames, predicts a duration class (12 logits, 11 durations plus an out-of-reach class that generation disables) and then the root path (measured, from the shapes and code). Then the decoder, which is a convolutional network, turns tokens, the root path and any pinned poses into 413 features per frame.
What one pass costs
The cards and the paper quote latency on GPUs. I can add one thing they do not, which is the reason it is cheap. I built the pose transformer with its real shapes and random weights in numpy, float32, 2 threads, on a shared 4-core box, and timed one forward pass of 6, 11 and 16 positions at batch sizes 1 and 8. The weights are random, so this says nothing about quality, only about cost, and it leaves out the root predictor and the decoder. Two runs, median of 15 calls each (measured):
| Positions | Work, per sample | Batch 1 | Batch 8 |
|---|---|---|---|
| 6 | 1.61 GFLOP | 364 and 368 ms | 1,212 and 1,404 ms |
| 11 | 2.96 GFLOP | 360 and 373 ms | 1,297 and 1,346 ms |
| 16 | 4.31 GFLOP | 343 and 374 ms | 1,274 and 1,399 ms |
The work column is counted from the shapes (reasoned). At batch 1 the pass takes the same time at 6 positions as at 16, though the arithmetic is 2.7 times larger. That is what a memory-bound layer looks like: 134.4 million float32 weights are 538 MB, they are read in full on every pass, and each weight is used for only a handful of positions. At batch 1 and 16 positions that is 8 FLOP per byte read (reasoned). Batch 8 does 8 times the work in about 3.5 times the time. The CPU here moved weights at roughly 1.5 GB/s, which is slow and says more about my shared box than about the model.
Now put that next to the reported numbers. The project's own trtexec table, on an RTX 4090 under Windows with the plan alone on the GPU, gives 2.67 ms for G1 in float32 at batch 1, 1.63 ms in mixed float16, and 7.81 ms and 3.38 ms at batch 32 (reported). The paper reports 2 ms latency and 15,000 frames per second on an RTX 5090 desktop, and 5 ms on a Jetson Orin for the robot (reported). I can only check these for consistency. A 4090's memory bandwidth is about 1 TB/s by NVIDIA's published figure, which I did not look up here, so reading 538 MB takes about 0.5 ms (reasoned). The reported 2.67 ms is five times that, so on the GPU the wall time is not just weight traffic, and the convolutional root and decoder networks and launch overhead must carry the rest. Float16 halves the bytes and cuts the time by 39% (2.67 to 1.63 ms), which fits a model that is part memory-bound and part something else. I did not profile it.
The 15,000 frames per second is a throughput figure. A clip is 24 to 64 frames, and 15,000 frames per second at 2 ms per call is 30 frames a call, a plausible average (reasoned). It is not 15,000 independent characters. The card's batch table says G1 float32 at batch 32 serves 4,097 requests per second, so the number depends on what you count.
What the paper claims
The paper's headline comparison is Table 3, on its 350,000-clip proprietary set, against five in-betweening baselines retrained by the authors (reported, I did not reproduce any of it). A selection of the rows:
| Method | Latency | FID, lower is better | Reaches target |
|---|---|---|---|
| MotionBricks | 2 ms | 1.054 | 99.6% |
| Closd-DiP | 15.3 ms | 1.292 | 75.7% |
| MMM (single-head tokens) | 18.1 ms | 1.544 | 34.8% |
| CondMDI | 33.2 ms | 1.213 | 61.3% |
A 40-person user study picks MotionBricks as the winner in 86.5% of trials, and a deterministic transformer baseline wins 5.0% (reported). Two cautions. The metrics are measured by the authors on a dataset the release does not include, and the models in these tables were trained separately from the shipped checkpoints. The G1 card says plainly that "a complete quantitative evaluation report for these checkpoint files is not included". The same card lists 4,881 validation clips drawn from a held-out pool and says a final untouched test set and a performer-disjoint split are "not documented". So the paper's numbers are evidence about the method, and the released weights come with no score of their own.
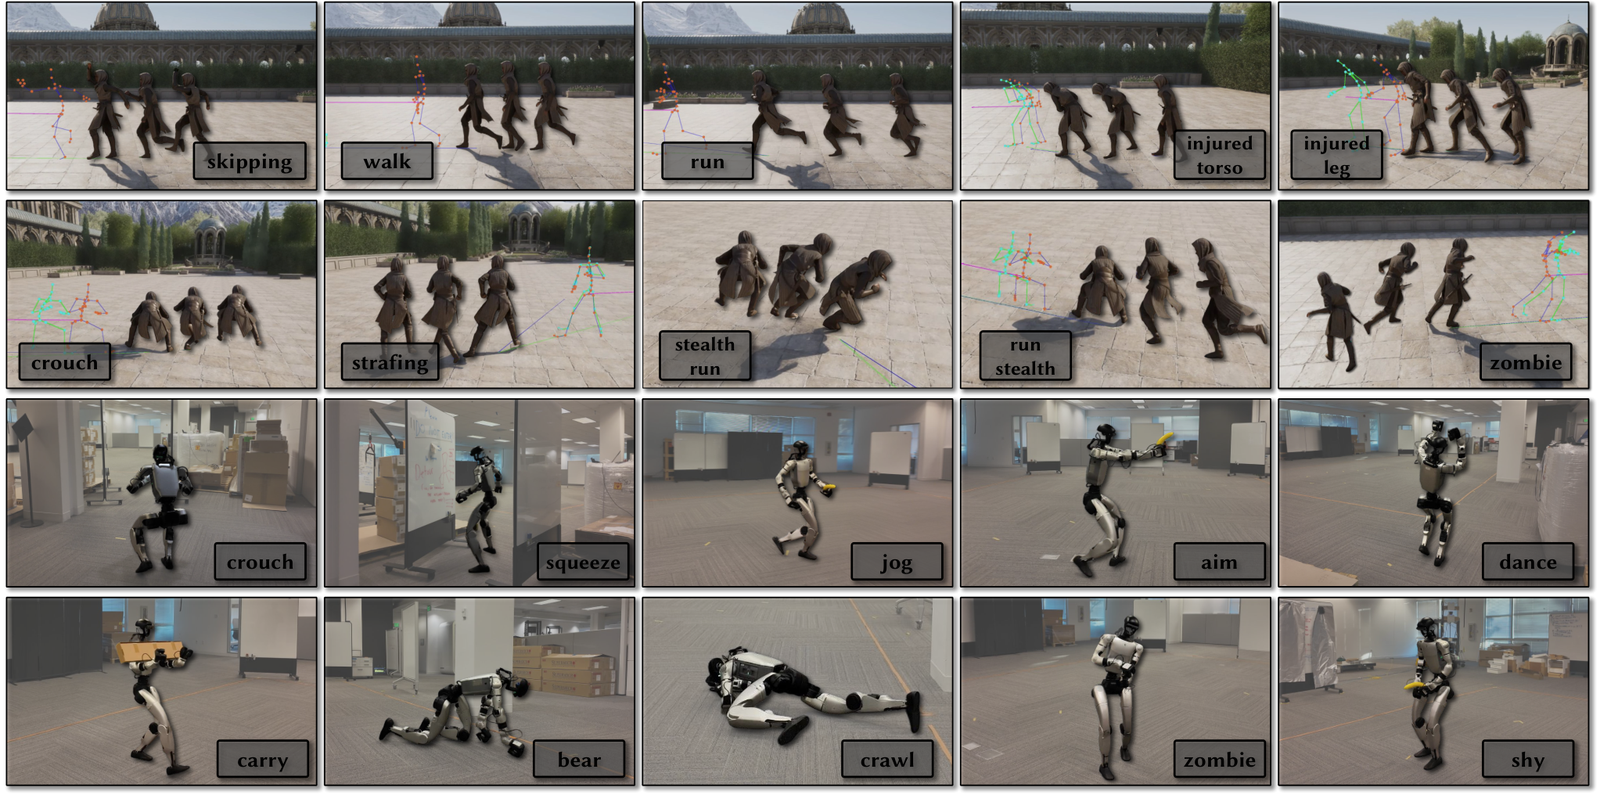
The paper also shows the G1 robot driven by the generated motion through a separate tracking controller (Figure 6 below).
What it does not do
All of this is from the cards, and I did not test any of it.
- It generates motion, not control. The README says "MotionBricks generates motion, not a controller for a physical robot". The poses do not enforce balance, actuator limits or collisions. The G1 card says the Newton integration has not been evaluated for tracking on a physical robot. You need a tracking controller, limit checks and your own validation.
- No text, no images, no scene. Conditioning is poses, masks and root constraints. Scene awareness lives in the application's smart primitives.
- It is bound to one skeleton. G1 weights need the G1's 34-joint layout and hinge order. SOMA and G1 files are not interchangeable.
- The demo motion bank is missing. The G1 package leaves out
G1-clip.ckpt, which the original demo needs, and the Bones samples are evaluation-only. - The training data is retargeted. The 313,526 training clips are human motion capture retargeted to G1 by software, not recorded from robots. The paper concedes that offline retargeting "requires months of iteration" and that its own automatic retargeting leaves artifacts (reported).
- Errors can feed back. Longer motion chains outputs into new context, and the card warns that precision and backend differences accumulate.
What I would do with it
If I wanted a kinematic reference generator for a humanoid, this is the first release I have read that gives the pieces: weights with a stated commercial licence, code under Apache 2.0, an exporter, and a TensorRT runtime. The cost is clear from the shapes. One 538 MB pose pass sets the floor, and on a GPU that is cheap, so an in-betweening call fits inside a control loop even at 10 Hz replanning. On a CPU it is hundreds of milliseconds by my measurement, so the Jetson-class path the paper describes depends on the TensorRT runtime, which needs an NVIDIA GPU.
The first thing I would check is determinism. Because the exported model takes an argmax in one pass, a regression test that pins a few context-and-target pairs and compares clips across precisions would show right away how much float16 changes the choice of codes. The card says it can change them. I would run that test before trusting float16 on a robot.
What I did not run
I did not run the model. There is no PyTorch here and no NVIDIA GPU, so I did not export the ONNX files, build a TensorRT plan, or generate a single clip, and I cannot say how the motion looks. I did not download the 546 MB pose checkpoint, to stay inside a disk budget, so the CPU timings use random weights of the real shapes. The timings come from two runs on a shared box with 2 threads and are an order-of-magnitude statement. The codebook shares are a moving-average proxy for usage. I did not check any of the paper's tables, the user study, or the robot demo. The Agreement text is as published on 27 October 2026 and could change.
# the headers are the whole experiment: 8 bytes of length, then JSON
import json, struct, urllib.request
def rng(u, a, b): return urllib.request.urlopen(urllib.request.Request(u, headers={"Range": f"bytes={a}-{b}"})).read()
n = struct.unpack("<Q", rng(URL, 0, 7))[0]
header = json.loads(rng(URL, 8, 8 + n - 1))  # tensor name -> dtype, shape, offsets